23 yo founder + researcher @ UT Austin, automating scientific research. Git contributor; coauthored work featured by Forbes. Owner of ASI the hamster 🐹
If I reopened the 2026 folder in 2030, I would check one thing first: did the work completed with AI change a real problem and leave evidence that others could verify and build upon?
Day 72 of Benchmark Radar. The daily snapshot archive has no record for October 6, 2026, so there are no verifiable fetched, published, or recommended counts, or research highlights, for this date.
Day seventy-one of Benchmark Radar. The daily scan published 560 records and recommended 273, led by “Passing the Test You Trained On,” a study of 15 prompt-injection detectors. Scoreboard: 279 stars, 45 forks.
Day seventy of Benchmark Radar. The daily scan published 484 records and recommended 127, led by the 2026 Cryo-EM Benchmark Dataset, 12 protein structures deposited after every disclosed test set for MICA. Scoreboard: 278 stars, 45 forks.
Day sixty-nine of Benchmark Radar. The daily scan published 577 records and recommended 174, led by an updated retinal benchmark audit that publishes image-level manifests and per-image predictions. Scoreboard: 275 stars, 45 forks.
Day sixty-eight of Benchmark Radar. The daily scan published 668 records and recommended 244, led by Video-Index, a meta-benchmark that audits whether video tests require video understanding. Scoreboard: 272 stars, 45 forks.
Day sixty-seven of Benchmark Radar. The daily scan published 688 records and recommended 289, led by “Dating the Model,” a study showing that a hidden current-date line changes measured performance. Scoreboard: 268 stars, 45 forks.
Day sixty-six of Benchmark Radar. The daily scan published 656 records and recommended 186, led by UserProxyBench, which tests whether the language model playing the user follows its private instructions. Scoreboard: 268 stars, 43 forks.
Day sixty-five of Benchmark Radar. The daily scan published 758 records and recommended 381, led by TraceDance, which turns real agent deployment traces into benchmarks for undesirable behavior. Scoreboard: 266 stars, 43 forks.
Day sixty-four of Benchmark Radar. The daily scan published 505 records and recommended 233, led by the Finance Agents Benchmark, which packages financial due diligence as an end-to-end agent test. Scoreboard: 264 stars, 42 forks.
Day sixty-three of Benchmark Radar. The daily scan published 314 records and recommended 106, led by the Kalyvox Voice Benchmark 2026, which scores one voice agent across 240 controlled calls. Scoreboard: 257 stars, 41 forks.
Day sixty-two of Benchmark Radar. The daily scan published 540 records and recommended 171, led by repo2bench, which turns Python repositories into coding-agent tasks. Scoreboard: 255 stars, 41 forks.
Day sixty-one of Benchmark Radar. The daily scan published 450 records and recommended 198, led by PartHackBench, which tests whether partial-credit scorers reward misleading progress in long-running tool agents. Scoreboard: 252 stars, 41 forks.
Day sixty of Benchmark Radar. Benchmark Radar reaches 250 stars on day sixty. The daily scan published 471 records and recommended 199, led by Uncheatable Eval, which scores models on text published after they were trained. Scoreboard: 250 stars, 41 forks.
Day fifty-nine of Benchmark Radar. The daily scan published 510 records and recommended 211, led by a molecular audit that finds hidden duplicates across train and test splits and a benchmark for coding agents whose patches break when merged. Scoreboard: 249 stars, 41 forks.
Day fifty-eight of Benchmark Radar. Two fixes clear yesterday’s stop without loosening the check that caused it: Zenodo file batches collapse to one finding, and copied Hugging Face template text no longer passes as a description. Scoreboard: 246 stars, 41 forks.
Day fifty-seven of Benchmark Radar. The daily run failed on purpose. A safety check found 16 records sharing one description and refused to publish them. Scoreboard: 238 stars, 41 forks.
Day fifty-six of Benchmark Radar. Contributor winklemad lands two fixes: one makes record-holder credit agree with the record chart, the other keeps every benchmark’s page address unique. Scoreboard: 236 stars, 41 forks.
Day fifty-five of Benchmark Radar. The contributor guide gains one rule: start every branch from an up-to-date main. The WeChat group QR code is refreshed, and the daily scan ran on schedule. Scoreboard: 234 stars, 40 forks.
Day fifty-four of Benchmark Radar. The daily scan published 618 records and recommended 224, including a 1.6-million-mask ultrasound release and OverclaimBench, a test of whether coding agents falsely report finished work. Scoreboard: 233 stars, 38 forks.
Day fifty-three of Benchmark Radar. The daily scan published 666 records and recommended 261 of them, led by a corrected word-sense benchmark, a stablecoin stress arena, and a ride-hailing agent test. Scoreboard: 229 stars, 36 forks.
Day fifty-two of Benchmark Radar. The dataset ships to Hugging Face with automated sync, and seventeen project-only words leave the interface for plain language. Scoreboard: 226 stars, 35 forks.
Day fifty-one of Benchmark Radar. A quiet day with loud groundwork: the daily snapshot recorded while the Hugging Face dataset export goes through validation. Scoreboard: 185 stars, 30 forks.
A laser lightsail accelerating to one percent of light speed turns about one percent of the beam into motion. The other ninety-nine percent leaves as light and does no work.
Day fifty of Benchmark Radar. The paper links point at arXiv everywhere, the README asks readers to upvote on Hugging Face, and a dated laurel badge marks the #1 Paper of the Day on the dashboard. Scoreboard: 185 stars, 30 forks.
Day forty-nine of Benchmark Radar. The README starts naming its readers: a researchers-by-institution strip with official logos, built by a script, plus a fresh WeChat group code for daily discussion. Scoreboard: 185 stars, 30 forks.
Day forty-eight of Benchmark Radar. The dashboard gets a reader-first pass: the homepage banner keeps its words but drops its pixels, benchmark pages answer what readers actually search for, and an About page tells the project’s story on the site. Scoreboard: 185 stars, 30 forks.
Day forty-seven of Benchmark Radar. With the arXiv paper live, the citation surfaces get a reader-first refresh: the Cite card collapses APA and BibTeX blocks by default, CITATION.md lands in the repo root, and a Cite link joins the top navigation bar. Scoreboard: 185 stars, 30 forks.
Day forty-six of Benchmark Radar. The technical paper is now on arXiv as arXiv:2609.11115, the v0.11.0 release is published with frozen data and verified hashes, and citation surfaces across the project update to the live arXiv entry. Scoreboard: 185 stars, 30 forks.
Day forty-five of Benchmark Radar. The paper enters its final preparation phase: content relicensed to CC BY-NC-SA 4.0, CI checks validate frozen paper data, and report tests align with the manuscript. Scoreboard: 180 stars, 32 forks.
Day forty-four of Benchmark Radar. The paper submodule advances through the citation revision and the source-count revision to the rebuilt PDF. The arXiv submission package assembles. Scoreboard: 175 stars, 31 forks.
Day forty-three of Benchmark Radar. The discovery cutoff for the technical paper locks at 2026-09-07. Source counts, figure data, and the full-catalog audit pipeline freeze for the v0.11.0 release and arXiv submission. Scoreboard: 170 stars, 30 forks.
Day forty-two of Benchmark Radar. The ranking engine for recent releases moves from backend to the dashboard, and the daily radar snapshot captures the first full week of ranked cohorts. Scoreboard: 165 stars, 29 forks.
Day forty-one of Benchmark Radar. The ranking engine for recent releases shipped its first phase with the data contract written first, and the report audit separated raw best scores from scores measured under the same protocol. Scoreboard: 160 stars, 28 forks.
Day forty of Benchmark Radar. The radar started watching the network where most new benchmark papers get their DOI, brought a benchmark back by searching its exact name, and started posting where it was not posting before. Scoreboard: 147 stars, 27 forks.
Day thirty-nine of Benchmark Radar. The daily brief now has a landing page, a full archive, and a feed of its own, and the dashboard navigation got short enough to scan. Scoreboard: 144 stars, 27 forks.
Day thirty-eight of Benchmark Radar. The daily brief, the thing the project already wrote every day and never gave a page, now has a blog and a feed. Scoreboard: 137 stars, 26 forks.
Day thirty-seven of Benchmark Radar. Anyone writing a paper can now copy a citation without leaving the dashboard, the offline setup moved onto the site, and search looks through every collected day by default. Scoreboard: 130 stars, 25 forks.
Day thirty-six of Benchmark Radar. The biggest model card yet landed with 37 scores across 34 benchmarks, and search stopped guessing which result answered the question. Scoreboard: 128 stars, 24 forks.
Day thirty-five of Benchmark Radar. A week-old copycat outranked the real project for its own name because search engines could see only four pages here. Today every one of the 1,173 benchmarks the radar tracks has a page of its own. Scoreboard: 123 stars, 23 forks.
Day thirty-four of Benchmark Radar. The radar now runs from a command line on your own computer, offline, no dashboard in between, and a coding agent can answer benchmark questions straight from the data. Scoreboard: 121 stars, 23 forks.
Day thirty-three of Benchmark Radar. The radar learned to find benchmark releases that keyword search would never catch, and a new frontier model card with 14 benchmarks joined the registry. Scoreboard: 115 stars, 21 forks.
Day thirty-two of Benchmark Radar. We fixed data errors that failed silently, taught the ranking to count adoption for releases that ship no binary files, and rewrote the daily briefing so it reads like a person wrote it. Scoreboard: 113 stars, 21 forks.
Day thirty-one of Benchmark Radar. Every release card now carries a one-line summary instead of a bare version tag, filing an issue takes at most two required fields, and both READMEs got short enough to read. Scoreboard: 107 stars, 20 forks.
There are only 26 single-letter .ai domains. I went through all of them, one by one, to see who actually builds something and who just squats. The answer: about six run real products, one belongs to Elon Musk, one belongs to Google, one apparently belongs to Apple without a website, and the rest are for-sale pages asking between 1.5 and 500 million dollars. Here is the full alphabet.
Day thirty of Benchmark Radar. Thirty posts in, this log has become a live broadcast of one open-source project trying to reach 1,000 stars, and today the scoreboard reads 86.
Day twenty-nine of Benchmark Radar. We ranked new releases before routine updates, put a 0 to 1 score on a 0 to 100 scale without changing its value, and made the active tab stay active.
Day twenty-seven of Benchmark Radar. We made the Today list load a page at a time, cut a title in half, and taught 21 benchmarks to show their real names.
Day twenty-six of Benchmark Radar. We put the ranking where it belongs, made the Back button work, and replaced an invented chart with one we can draw.
Day twenty-five of Benchmark Radar. We stopped the radar from ranking itself, put scores on the dates they belong to, and let a benchmark with no score still speak for itself.
Day seven was the biggest single day. Hi, Koutian here. We launched a new leaderboard, grew the registry to the 2026 frontier, and bumped the version to 0.3.0.
The most valuable application of LLMs may not be answering questions, but turning an expert job into a digital work unit that can be executed, reviewed, and audited.
When someone publicly told Steve Jobs that he did not understand technology, Jobs paused, conceded part of the criticism, and asked a more consequential question: what will the customer ultimately gain?
The thing that almost stranded me on this international trip was not a typhoon, but several unrelated systems deciding at the same time that they did not trust me.
Does building a benchmark count as research, or is it “crowdfunding a paper”? Does it create public value or consume public resources? Can it build lasting capabilities, or is it useful only for a startup team trying to show investors its potential?
The most dangerous failure mode of an AI science benchmark is not that it is too hard, it is that it quietly becomes either a coding trick or a guessing game.
Compute / tokens are the new generation of free eggs. Right now all the big vendors are handing out compute like they’re handing out eggs. When you’re old, you’ll be fighting other old grannies and grandpas for free eggs, this is no longer just a joke, it might be reality.
When you go looking for a seat in the great theater of the AI era, built from PowerPoints, papers, and anxiety, it helps to look at which play each person on stage is performing.
I spent the last couple of days checking a tempting claim: that Microsoft Flight Simulator is secretly the foundation for a broader Earth digital twin story.
Anthropic’s most ruthless move isn’t polishing every product to perfection before release, but daring to throw out a research preview first, then rapidly getting stronger in front of everyone.
When an AI writing assistant turns a paper’s incoherent rambling into a “well-structured pile of something,” we have to admit: it is basically a cyber laxative.
I was in the middle of setting up a second Cloudflare backup, verifying one dataset and configuring another, when the AI agent helping me flagged something unrelated: while listing what had access to my GitHub account, one authorization stood out as unusually broad. That single flag turned into an hour of reviewing GitHub’s installed-apps list, and it was worth every minute.
I ran a health check on my Claude Code setup this week and found 174 custom skills, 124 of which I had never invoked once. They were not failures. Most of them were scaffolding I built for a model that needed it, and then kept long after the model stopped needing it.
One account opened 58 pull requests in 10 days on benchmark-radar. Five were merged. I put the contribution policy into agent-pr-gate so other maintainers can copy it: before an AI agent starts PR work, it asks its human four questions and waits for the answers.
You apply to Anthropic, land an offer, then ask HR whether they’ll sponsor your PERM, and they say “on hold for now” or change the subject, and you probably stand there frozen.
The most dangerous failure mode of an AI science benchmark is not that it is too hard, it is that it quietly becomes either a coding trick or a guessing game.
Anthropic’s most ruthless move isn’t polishing every product to perfection before release, but daring to throw out a research preview first, then rapidly getting stronger in front of everyone.
You apply to Anthropic, land an offer, then ask HR whether they’ll sponsor your PERM, and they say “on hold for now” or change the subject, and you probably stand there frozen.
When someone publicly told Steve Jobs that he did not understand technology, Jobs paused, conceded part of the criticism, and asked a more consequential question: what will the customer ultimately gain?
Day forty-three of Benchmark Radar. The discovery cutoff for the technical paper locks at 2026-09-07. Source counts, figure data, and the full-catalog audit pipeline freeze for the v0.11.0 release and arXiv submission. Scoreboard: 170 stars, 30 forks.
Day forty-one of Benchmark Radar. The ranking engine for recent releases shipped its first phase with the data contract written first, and the report audit separated raw best scores from scores measured under the same protocol. Scoreboard: 160 stars, 28 forks.
Does building a benchmark count as research, or is it “crowdfunding a paper”? Does it create public value or consume public resources? Can it build lasting capabilities, or is it useful only for a startup team trying to show investors its potential?
The most dangerous failure mode of an AI science benchmark is not that it is too hard, it is that it quietly becomes either a coding trick or a guessing game.
Day 72 of Benchmark Radar. The daily snapshot archive has no record for October 6, 2026, so there are no verifiable fetched, published, or recommended counts, or research highlights, for this date.
Day seventy-one of Benchmark Radar. The daily scan published 560 records and recommended 273, led by “Passing the Test You Trained On,” a study of 15 prompt-injection detectors. Scoreboard: 279 stars, 45 forks.
Day seventy of Benchmark Radar. The daily scan published 484 records and recommended 127, led by the 2026 Cryo-EM Benchmark Dataset, 12 protein structures deposited after every disclosed test set for MICA. Scoreboard: 278 stars, 45 forks.
Day sixty-nine of Benchmark Radar. The daily scan published 577 records and recommended 174, led by an updated retinal benchmark audit that publishes image-level manifests and per-image predictions. Scoreboard: 275 stars, 45 forks.
Day sixty-eight of Benchmark Radar. The daily scan published 668 records and recommended 244, led by Video-Index, a meta-benchmark that audits whether video tests require video understanding. Scoreboard: 272 stars, 45 forks.
Day sixty-seven of Benchmark Radar. The daily scan published 688 records and recommended 289, led by “Dating the Model,” a study showing that a hidden current-date line changes measured performance. Scoreboard: 268 stars, 45 forks.
Day sixty-six of Benchmark Radar. The daily scan published 656 records and recommended 186, led by UserProxyBench, which tests whether the language model playing the user follows its private instructions. Scoreboard: 268 stars, 43 forks.
Day sixty-five of Benchmark Radar. The daily scan published 758 records and recommended 381, led by TraceDance, which turns real agent deployment traces into benchmarks for undesirable behavior. Scoreboard: 266 stars, 43 forks.
Day sixty-four of Benchmark Radar. The daily scan published 505 records and recommended 233, led by the Finance Agents Benchmark, which packages financial due diligence as an end-to-end agent test. Scoreboard: 264 stars, 42 forks.
Day sixty-three of Benchmark Radar. The daily scan published 314 records and recommended 106, led by the Kalyvox Voice Benchmark 2026, which scores one voice agent across 240 controlled calls. Scoreboard: 257 stars, 41 forks.
Day sixty-two of Benchmark Radar. The daily scan published 540 records and recommended 171, led by repo2bench, which turns Python repositories into coding-agent tasks. Scoreboard: 255 stars, 41 forks.
Day sixty-one of Benchmark Radar. The daily scan published 450 records and recommended 198, led by PartHackBench, which tests whether partial-credit scorers reward misleading progress in long-running tool agents. Scoreboard: 252 stars, 41 forks.
Day sixty of Benchmark Radar. Benchmark Radar reaches 250 stars on day sixty. The daily scan published 471 records and recommended 199, led by Uncheatable Eval, which scores models on text published after they were trained. Scoreboard: 250 stars, 41 forks.
Day fifty-nine of Benchmark Radar. The daily scan published 510 records and recommended 211, led by a molecular audit that finds hidden duplicates across train and test splits and a benchmark for coding agents whose patches break when merged. Scoreboard: 249 stars, 41 forks.
Day fifty-eight of Benchmark Radar. Two fixes clear yesterday’s stop without loosening the check that caused it: Zenodo file batches collapse to one finding, and copied Hugging Face template text no longer passes as a description. Scoreboard: 246 stars, 41 forks.
Day fifty-seven of Benchmark Radar. The daily run failed on purpose. A safety check found 16 records sharing one description and refused to publish them. Scoreboard: 238 stars, 41 forks.
Day fifty-six of Benchmark Radar. Contributor winklemad lands two fixes: one makes record-holder credit agree with the record chart, the other keeps every benchmark’s page address unique. Scoreboard: 236 stars, 41 forks.
Day fifty-five of Benchmark Radar. The contributor guide gains one rule: start every branch from an up-to-date main. The WeChat group QR code is refreshed, and the daily scan ran on schedule. Scoreboard: 234 stars, 40 forks.
Day fifty-four of Benchmark Radar. The daily scan published 618 records and recommended 224, including a 1.6-million-mask ultrasound release and OverclaimBench, a test of whether coding agents falsely report finished work. Scoreboard: 233 stars, 38 forks.
Day fifty-three of Benchmark Radar. The daily scan published 666 records and recommended 261 of them, led by a corrected word-sense benchmark, a stablecoin stress arena, and a ride-hailing agent test. Scoreboard: 229 stars, 36 forks.
Day fifty-two of Benchmark Radar. The dataset ships to Hugging Face with automated sync, and seventeen project-only words leave the interface for plain language. Scoreboard: 226 stars, 35 forks.
Day fifty-one of Benchmark Radar. A quiet day with loud groundwork: the daily snapshot recorded while the Hugging Face dataset export goes through validation. Scoreboard: 185 stars, 30 forks.
Day fifty of Benchmark Radar. The paper links point at arXiv everywhere, the README asks readers to upvote on Hugging Face, and a dated laurel badge marks the #1 Paper of the Day on the dashboard. Scoreboard: 185 stars, 30 forks.
Day forty-nine of Benchmark Radar. The README starts naming its readers: a researchers-by-institution strip with official logos, built by a script, plus a fresh WeChat group code for daily discussion. Scoreboard: 185 stars, 30 forks.
Day forty-eight of Benchmark Radar. The dashboard gets a reader-first pass: the homepage banner keeps its words but drops its pixels, benchmark pages answer what readers actually search for, and an About page tells the project’s story on the site. Scoreboard: 185 stars, 30 forks.
Day forty-seven of Benchmark Radar. With the arXiv paper live, the citation surfaces get a reader-first refresh: the Cite card collapses APA and BibTeX blocks by default, CITATION.md lands in the repo root, and a Cite link joins the top navigation bar. Scoreboard: 185 stars, 30 forks.
Day forty-six of Benchmark Radar. The technical paper is now on arXiv as arXiv:2609.11115, the v0.11.0 release is published with frozen data and verified hashes, and citation surfaces across the project update to the live arXiv entry. Scoreboard: 185 stars, 30 forks.
Day forty-five of Benchmark Radar. The paper enters its final preparation phase: content relicensed to CC BY-NC-SA 4.0, CI checks validate frozen paper data, and report tests align with the manuscript. Scoreboard: 180 stars, 32 forks.
Day forty-four of Benchmark Radar. The paper submodule advances through the citation revision and the source-count revision to the rebuilt PDF. The arXiv submission package assembles. Scoreboard: 175 stars, 31 forks.
Day forty-three of Benchmark Radar. The discovery cutoff for the technical paper locks at 2026-09-07. Source counts, figure data, and the full-catalog audit pipeline freeze for the v0.11.0 release and arXiv submission. Scoreboard: 170 stars, 30 forks.
Day forty-two of Benchmark Radar. The ranking engine for recent releases moves from backend to the dashboard, and the daily radar snapshot captures the first full week of ranked cohorts. Scoreboard: 165 stars, 29 forks.
Day forty-one of Benchmark Radar. The ranking engine for recent releases shipped its first phase with the data contract written first, and the report audit separated raw best scores from scores measured under the same protocol. Scoreboard: 160 stars, 28 forks.
Day forty of Benchmark Radar. The radar started watching the network where most new benchmark papers get their DOI, brought a benchmark back by searching its exact name, and started posting where it was not posting before. Scoreboard: 147 stars, 27 forks.
Day thirty-nine of Benchmark Radar. The daily brief now has a landing page, a full archive, and a feed of its own, and the dashboard navigation got short enough to scan. Scoreboard: 144 stars, 27 forks.
Day thirty-eight of Benchmark Radar. The daily brief, the thing the project already wrote every day and never gave a page, now has a blog and a feed. Scoreboard: 137 stars, 26 forks.
Day thirty-seven of Benchmark Radar. Anyone writing a paper can now copy a citation without leaving the dashboard, the offline setup moved onto the site, and search looks through every collected day by default. Scoreboard: 130 stars, 25 forks.
Day thirty-six of Benchmark Radar. The biggest model card yet landed with 37 scores across 34 benchmarks, and search stopped guessing which result answered the question. Scoreboard: 128 stars, 24 forks.
Day thirty-five of Benchmark Radar. A week-old copycat outranked the real project for its own name because search engines could see only four pages here. Today every one of the 1,173 benchmarks the radar tracks has a page of its own. Scoreboard: 123 stars, 23 forks.
Day thirty-four of Benchmark Radar. The radar now runs from a command line on your own computer, offline, no dashboard in between, and a coding agent can answer benchmark questions straight from the data. Scoreboard: 121 stars, 23 forks.
Day thirty-three of Benchmark Radar. The radar learned to find benchmark releases that keyword search would never catch, and a new frontier model card with 14 benchmarks joined the registry. Scoreboard: 115 stars, 21 forks.
Day thirty-two of Benchmark Radar. We fixed data errors that failed silently, taught the ranking to count adoption for releases that ship no binary files, and rewrote the daily briefing so it reads like a person wrote it. Scoreboard: 113 stars, 21 forks.
Day thirty-one of Benchmark Radar. Every release card now carries a one-line summary instead of a bare version tag, filing an issue takes at most two required fields, and both READMEs got short enough to read. Scoreboard: 107 stars, 20 forks.
Day thirty of Benchmark Radar. Thirty posts in, this log has become a live broadcast of one open-source project trying to reach 1,000 stars, and today the scoreboard reads 86.
Day twenty-nine of Benchmark Radar. We ranked new releases before routine updates, put a 0 to 1 score on a 0 to 100 scale without changing its value, and made the active tab stay active.
Day twenty-seven of Benchmark Radar. We made the Today list load a page at a time, cut a title in half, and taught 21 benchmarks to show their real names.
Day twenty-six of Benchmark Radar. We put the ranking where it belongs, made the Back button work, and replaced an invented chart with one we can draw.
Day twenty-five of Benchmark Radar. We stopped the radar from ranking itself, put scores on the dates they belong to, and let a benchmark with no score still speak for itself.
Day seven was the biggest single day. Hi, Koutian here. We launched a new leaderboard, grew the registry to the 2026 frontier, and bumped the version to 0.3.0.
Day thirty-nine of Benchmark Radar. The daily brief now has a landing page, a full archive, and a feed of its own, and the dashboard navigation got short enough to scan. Scoreboard: 144 stars, 27 forks.
Day thirty-eight of Benchmark Radar. The daily brief, the thing the project already wrote every day and never gave a page, now has a blog and a feed. Scoreboard: 137 stars, 26 forks.
Day thirty-two of Benchmark Radar. We fixed data errors that failed silently, taught the ranking to count adoption for releases that ship no binary files, and rewrote the daily briefing so it reads like a person wrote it. Scoreboard: 113 stars, 21 forks.
Day twenty-nine of Benchmark Radar. We ranked new releases before routine updates, put a 0 to 1 score on a 0 to 100 scale without changing its value, and made the active tab stay active.
A junior colleague asked me recently if there is a magical brokerage that does it all, from stock trading to high-yield savings, which reminded me of my own naive expectations when I first started investing.
A street vendor earns a markup. A person who builds a company earns a valuation. Between the two sits one question: who gets other people’s money first.
Day forty-five of Benchmark Radar. The paper enters its final preparation phase: content relicensed to CC BY-NC-SA 4.0, CI checks validate frozen paper data, and report tests align with the manuscript. Scoreboard: 180 stars, 32 forks.
Day thirty-eight of Benchmark Radar. The daily brief, the thing the project already wrote every day and never gave a page, now has a blog and a feed. Scoreboard: 137 stars, 26 forks.
Day thirty-seven of Benchmark Radar. Anyone writing a paper can now copy a citation without leaving the dashboard, the offline setup moved onto the site, and search looks through every collected day by default. Scoreboard: 130 stars, 25 forks.
Day thirty-four of Benchmark Radar. The radar now runs from a command line on your own computer, offline, no dashboard in between, and a coding agent can answer benchmark questions straight from the data. Scoreboard: 121 stars, 23 forks.
Does building a benchmark count as research, or is it “crowdfunding a paper”? Does it create public value or consume public resources? Can it build lasting capabilities, or is it useful only for a startup team trying to show investors its potential?
Day twenty-six of Benchmark Radar. We put the ranking where it belongs, made the Back button work, and replaced an invented chart with one we can draw.
Day fifty-nine of Benchmark Radar. The daily scan published 510 records and recommended 211, led by a molecular audit that finds hidden duplicates across train and test splits and a benchmark for coding agents whose patches break when merged. Scoreboard: 249 stars, 41 forks.
Day forty-seven of Benchmark Radar. With the arXiv paper live, the citation surfaces get a reader-first refresh: the Cite card collapses APA and BibTeX blocks by default, CITATION.md lands in the repo root, and a Cite link joins the top navigation bar. Scoreboard: 185 stars, 30 forks.
Day forty-four of Benchmark Radar. The paper submodule advances through the citation revision and the source-count revision to the rebuilt PDF. The arXiv submission package assembles. Scoreboard: 175 stars, 31 forks.
Day thirty-seven of Benchmark Radar. Anyone writing a paper can now copy a citation without leaving the dashboard, the offline setup moved onto the site, and search looks through every collected day by default. Scoreboard: 130 stars, 25 forks.
At today’s Silicon Valley alumni “Ask a Question” AI meet-up, what I wanted to talk about wasn’t how cool Claude Code is, but how it actually re-slices real work.
I ran a health check on my Claude Code setup this week and found 174 custom skills, 124 of which I had never invoked once. They were not failures. Most of them were scaffolding I built for a model that needed it, and then kept long after the model stopped needing it.
Anthropic’s most ruthless move isn’t polishing every product to perfection before release, but daring to throw out a research preview first, then rapidly getting stronger in front of everyone.
At today’s Silicon Valley alumni “Ask a Question” AI meet-up, what I wanted to talk about wasn’t how cool Claude Code is, but how it actually re-slices real work.
I was in the middle of setting up a second Cloudflare backup, verifying one dataset and configuring another, when the AI agent helping me flagged something unrelated: while listing what had access to my GitHub account, one authorization stood out as unusually broad. That single flag turned into an hour of reviewing GitHub’s installed-apps list, and it was worth every minute.
Day fifty-nine of Benchmark Radar. The daily scan published 510 records and recommended 211, led by a molecular audit that finds hidden duplicates across train and test splits and a benchmark for coding agents whose patches break when merged. Scoreboard: 249 stars, 41 forks.
Day fifty-four of Benchmark Radar. The daily scan published 618 records and recommended 224, including a 1.6-million-mask ultrasound release and OverclaimBench, a test of whether coding agents falsely report finished work. Scoreboard: 233 stars, 38 forks.
Most of biology is averages. You measure a million cells, you get a mean. Eric Greene’s lab figured out how to actually watch one DNA molecule at a time, repair itself, in real time, and that changes what kind of questions biology can ask.
Day forty-nine of Benchmark Radar. The README starts naming its readers: a researchers-by-institution strip with official logos, built by a script, plus a fresh WeChat group code for daily discussion. Scoreboard: 185 stars, 30 forks.
I ran a health check on my Claude Code setup this week and found 174 custom skills, 124 of which I had never invoked once. They were not failures. Most of them were scaffolding I built for a model that needed it, and then kept long after the model stopped needing it.
Day thirty-five of Benchmark Radar. A week-old copycat outranked the real project for its own name because search engines could see only four pages here. Today every one of the 1,173 benchmarks the radar tracks has a page of its own. Scoreboard: 123 stars, 23 forks.
Day fifty-six of Benchmark Radar. Contributor winklemad lands two fixes: one makes record-holder credit agree with the record chart, the other keeps every benchmark’s page address unique. Scoreboard: 236 stars, 41 forks.
Day fifty-five of Benchmark Radar. The contributor guide gains one rule: start every branch from an up-to-date main. The WeChat group QR code is refreshed, and the daily scan ran on schedule. Scoreboard: 234 stars, 40 forks.
Some books leave behind a few ideas. The Mom Test gave me a method I continue to use: do not ask whether someone likes your idea. Ask what they have already done, how often the problem occurs, what it has cost them, and whether they will commit to a next step.
Most of biology is averages. You measure a million cells, you get a mean. Eric Greene’s lab figured out how to actually watch one DNA molecule at a time, repair itself, in real time, and that changes what kind of questions biology can ask.
Day fifty-three of Benchmark Radar. The daily scan published 666 records and recommended 261 of them, led by a corrected word-sense benchmark, a stablecoin stress arena, and a ride-hailing agent test. Scoreboard: 229 stars, 36 forks.
Day forty-two of Benchmark Radar. The ranking engine for recent releases moves from backend to the dashboard, and the daily radar snapshot captures the first full week of ranked cohorts. Scoreboard: 165 stars, 29 forks.
Day thirty-nine of Benchmark Radar. The daily brief now has a landing page, a full archive, and a feed of its own, and the dashboard navigation got short enough to scan. Scoreboard: 144 stars, 27 forks.
Day forty-three of Benchmark Radar. The discovery cutoff for the technical paper locks at 2026-09-07. Source counts, figure data, and the full-catalog audit pipeline freeze for the v0.11.0 release and arXiv submission. Scoreboard: 170 stars, 30 forks.
Day thirty-one of Benchmark Radar. Every release card now carries a one-line summary instead of a bare version tag, filing an issue takes at most two required fields, and both READMEs got short enough to read. Scoreboard: 107 stars, 20 forks.
Day fifty-eight of Benchmark Radar. Two fixes clear yesterday’s stop without loosening the check that caused it: Zenodo file batches collapse to one finding, and copied Hugging Face template text no longer passes as a description. Scoreboard: 246 stars, 41 forks.
Day fifty-seven of Benchmark Radar. The daily run failed on purpose. A safety check found 16 records sharing one description and refused to publish them. Scoreboard: 238 stars, 41 forks.
Day forty-one of Benchmark Radar. The ranking engine for recent releases shipped its first phase with the data contract written first, and the report audit separated raw best scores from scores measured under the same protocol. Scoreboard: 160 stars, 28 forks.
Day thirty-six of Benchmark Radar. The biggest model card yet landed with 37 scores across 34 benchmarks, and search stopped guessing which result answered the question. Scoreboard: 128 stars, 24 forks.
Day thirty-two of Benchmark Radar. We fixed data errors that failed silently, taught the ranking to count adoption for releases that ship no binary files, and rewrote the daily briefing so it reads like a person wrote it. Scoreboard: 113 stars, 21 forks.
Day fifty-two of Benchmark Radar. The dataset ships to Hugging Face with automated sync, and seventeen project-only words leave the interface for plain language. Scoreboard: 226 stars, 35 forks.
Day fifty-one of Benchmark Radar. A quiet day with loud groundwork: the daily snapshot recorded while the Hugging Face dataset export goes through validation. Scoreboard: 185 stars, 30 forks.
Day twenty-five of Benchmark Radar. We stopped the radar from ranking itself, put scores on the dates they belong to, and let a benchmark with no score still speak for itself.
I ran a health check on my Claude Code setup this week and found 174 custom skills, 124 of which I had never invoked once. They were not failures. Most of them were scaffolding I built for a model that needed it, and then kept long after the model stopped needing it.
I spent the last couple of days checking a tempting claim: that Microsoft Flight Simulator is secretly the foundation for a broader Earth digital twin story.
Day forty of Benchmark Radar. The radar started watching the network where most new benchmark papers get their DOI, brought a benchmark back by searching its exact name, and started posting where it was not posting before. Scoreboard: 147 stars, 27 forks.
Day thirty-three of Benchmark Radar. The radar learned to find benchmark releases that keyword search would never catch, and a new frontier model card with 14 benchmarks joined the registry. Scoreboard: 115 stars, 21 forks.
Day thirty of Benchmark Radar. Thirty posts in, this log has become a live broadcast of one open-source project trying to reach 1,000 stars, and today the scoreboard reads 86.
Day forty-eight of Benchmark Radar. The dashboard gets a reader-first pass: the homepage banner keeps its words but drops its pixels, benchmark pages answer what readers actually search for, and an About page tells the project’s story on the site. Scoreboard: 185 stars, 30 forks.
Day forty-seven of Benchmark Radar. With the arXiv paper live, the citation surfaces get a reader-first refresh: the Cite card collapses APA and BibTeX blocks by default, CITATION.md lands in the repo root, and a Cite link joins the top navigation bar. Scoreboard: 185 stars, 30 forks.
There are only 26 single-letter .ai domains. I went through all of them, one by one, to see who actually builds something and who just squats. The answer: about six run real products, one belongs to Elon Musk, one belongs to Google, one apparently belongs to Apple without a website, and the rest are for-sale pages asking between 1.5 and 500 million dollars. Here is the full alphabet.
Most VCs and accelerators talk about supporting founders. Kehan Dong specifically supports the kind of founder who started building at 16, when nobody told them they were allowed to, and it turns out that population is dramatically underserved.
“The laws of physics look the same in every coordinate system” sounds like a platitude, yet Einstein fought over it for eight years and, halfway through, published a proof that it could not be done.
A widely shared post describes a brainstorming meeting at a robotics startup in Boston. A slide said “No stupid questions.” A Chinese employee interpreted it as “Do not ask stupid questions,” while American colleagues explained it as “Ask freely; no question will be judged stupid.” A related post claims that “Say it again?” is neutral when someone is not heard, whereas “What did you say?” is hostile.
一张流传截图讲了这样一件事:一家波士顿机器人创业公司开头脑风暴会,幻灯片写着 “No stupid questions.” 一位中国员工把它理解为“不要问蠢问题”,美国同事却说它的意思是“什么都可以问,没有问题会被当成蠢问题”。另一组讨论又声称:没听清时说 “Say it again?” 很中性,而 “What did you say?” 很不友好。
The most valuable application of LLMs may not be answering questions, but turning an expert job into a digital work unit that can be executed, reviewed, and audited.
The most dangerous failure mode of an AI science benchmark is not that it is too hard, it is that it quietly becomes either a coding trick or a guessing game.
You apply to Anthropic, land an offer, then ask HR whether they’ll sponsor your PERM, and they say “on hold for now” or change the subject, and you probably stand there frozen.
Another day of heavy internet surfing, and the biggest lesson was this: there is no investment strategy that lets you lie down and get financially free.
Day twenty-five of Benchmark Radar. We stopped the radar from ranking itself, put scores on the dates they belong to, and let a benchmark with no score still speak for itself.
A street vendor earns a markup. A person who builds a company earns a valuation. Between the two sits one question: who gets other people’s money first.
A junior colleague asked me recently if there is a magical brokerage that does it all, from stock trading to high-yield savings, which reminded me of my own naive expectations when I first started investing.
A receipt in Singapore showed S$5.50, while a U.S. credit-card account displayed only US$4.27. Another purchase of about S$48 appeared as roughly US$38. A bank-card transit ride also failed to appear immediately as pending.
“The laws of physics look the same in every coordinate system” sounds like a platitude, yet Einstein fought over it for eight years and, halfway through, published a proof that it could not be done.
The same way text foundation models ate NLP and image models ate computer vision, someone is going to build the foundation model that eats spatial reasoning. Gengchen Mai is one of the people taking that bet seriously, and his SEAI Lab at UT Austin is one of the places it is being built.
I was in the middle of setting up a second Cloudflare backup, verifying one dataset and configuring another, when the AI agent helping me flagged something unrelated: while listing what had access to my GitHub account, one authorization stood out as unusually broad. That single flag turned into an hour of reviewing GitHub’s installed-apps list, and it was worth every minute.
Day thirty of Benchmark Radar. Thirty posts in, this log has become a live broadcast of one open-source project trying to reach 1,000 stars, and today the scoreboard reads 86.
A street vendor earns a markup. A person who builds a company earns a valuation. Between the two sits one question: who gets other people’s money first.
Day fifty-eight of Benchmark Radar. Two fixes clear yesterday’s stop without loosening the check that caused it: Zenodo file batches collapse to one finding, and copied Hugging Face template text no longer passes as a description. Scoreboard: 246 stars, 41 forks.
Day fifty-two of Benchmark Radar. The dataset ships to Hugging Face with automated sync, and seventeen project-only words leave the interface for plain language. Scoreboard: 226 stars, 35 forks.
Day fifty-one of Benchmark Radar. A quiet day with loud groundwork: the daily snapshot recorded while the Hugging Face dataset export goes through validation. Scoreboard: 185 stars, 30 forks.
Day fifty of Benchmark Radar. The paper links point at arXiv everywhere, the README asks readers to upvote on Hugging Face, and a dated laurel badge marks the #1 Paper of the Day on the dashboard. Scoreboard: 185 stars, 30 forks.
Day twenty-five of Benchmark Radar. We stopped the radar from ranking itself, put scores on the dates they belong to, and let a benchmark with no score still speak for itself.
The story goes like this: I’ve been pondering a question lately—given how insanely advanced technology is today, why do we still have to spend so much time dressing up and managing our personal image?
A new paper looked at 739 science Nobel laureates from 1901 to 2023, and the headline number that came out is brutal, at the current rate of progress it would take roughly 600 years before a kid born into a poor country has the same shot at a Nobel as a kid born into a rich one.
A junior colleague asked me recently if there is a magical brokerage that does it all, from stock trading to high-yield savings, which reminded me of my own naive expectations when I first started investing.
Most academic climate scientists will tell you they care about policy and then publish a paper that no policymaker is ever going to read. Geeta Persad spent four years working at the Union of Concerned Scientists translating climate models for water managers, and she came back to academia knowing exactly what the gap looks like.
The most valuable application of LLMs may not be answering questions, but turning an expert job into a digital work unit that can be executed, reviewed, and audited.
The most valuable application of LLMs may not be answering questions, but turning an expert job into a digital work unit that can be executed, reviewed, and audited.
Day twenty-six of Benchmark Radar. We put the ranking where it belongs, made the Back button work, and replaced an invented chart with one we can draw.
Day seven was the biggest single day. Hi, Koutian here. We launched a new leaderboard, grew the registry to the 2026 frontier, and bumped the version to 0.3.0.
When someone publicly told Steve Jobs that he did not understand technology, Jobs paused, conceded part of the criticism, and asked a more consequential question: what will the customer ultimately gain?
Day forty-five of Benchmark Radar. The paper enters its final preparation phase: content relicensed to CC BY-NC-SA 4.0, CI checks validate frozen paper data, and report tests align with the manuscript. Scoreboard: 180 stars, 32 forks.
Day fifty-four of Benchmark Radar. The daily scan published 618 records and recommended 224, including a 1.6-million-mask ultrasound release and OverclaimBench, a test of whether coding agents falsely report finished work. Scoreboard: 233 stars, 38 forks.
I spent the last couple of days checking a tempting claim: that Microsoft Flight Simulator is secretly the foundation for a broader Earth digital twin story.
Day sixty of Benchmark Radar. Benchmark Radar reaches 250 stars on day sixty. The daily scan published 471 records and recommended 199, led by Uncheatable Eval, which scores models on text published after they were trained. Scoreboard: 250 stars, 41 forks.
Day thirty-six of Benchmark Radar. The biggest model card yet landed with 37 scores across 34 benchmarks, and search stopped guessing which result answered the question. Scoreboard: 128 stars, 24 forks.
Day thirty-three of Benchmark Radar. The radar learned to find benchmark releases that keyword search would never catch, and a new frontier model card with 14 benchmarks joined the registry. Scoreboard: 115 stars, 21 forks.
Day seven was the biggest single day. Hi, Koutian here. We launched a new leaderboard, grew the registry to the 2026 frontier, and bumped the version to 0.3.0.
One hundred twenty-six thousand eight hundred and eighty-seven dollars is housing-level money in Austin; in UT Austin’s new business-school building, it buys a single parking spot.
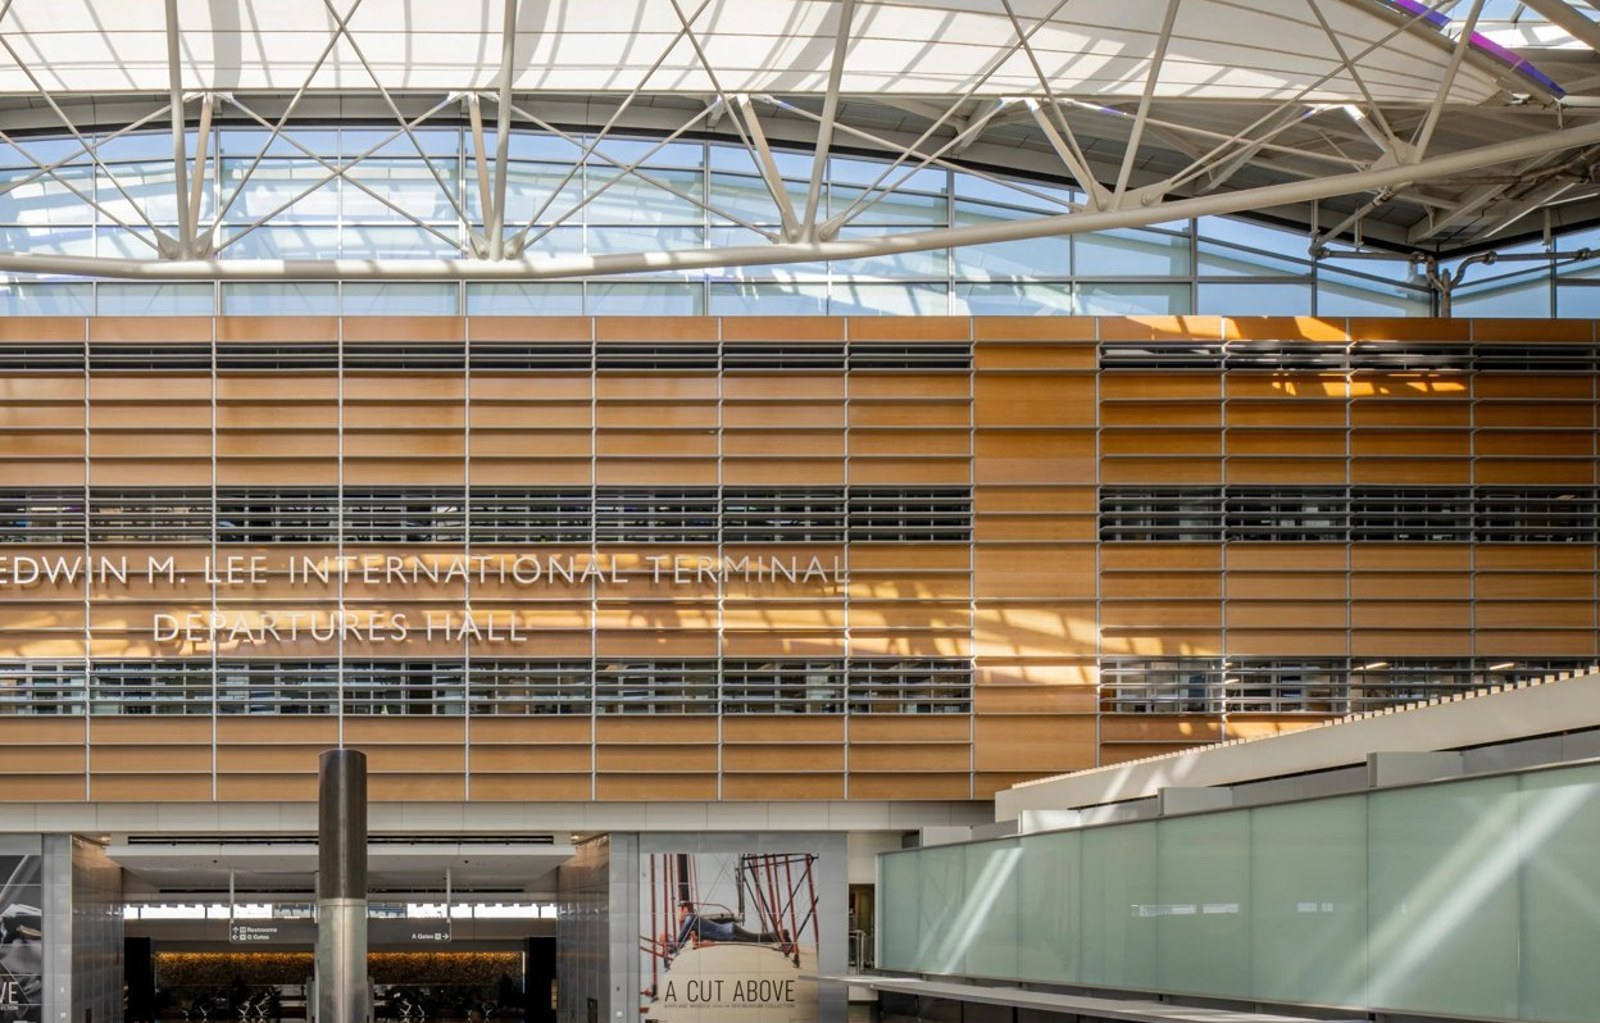
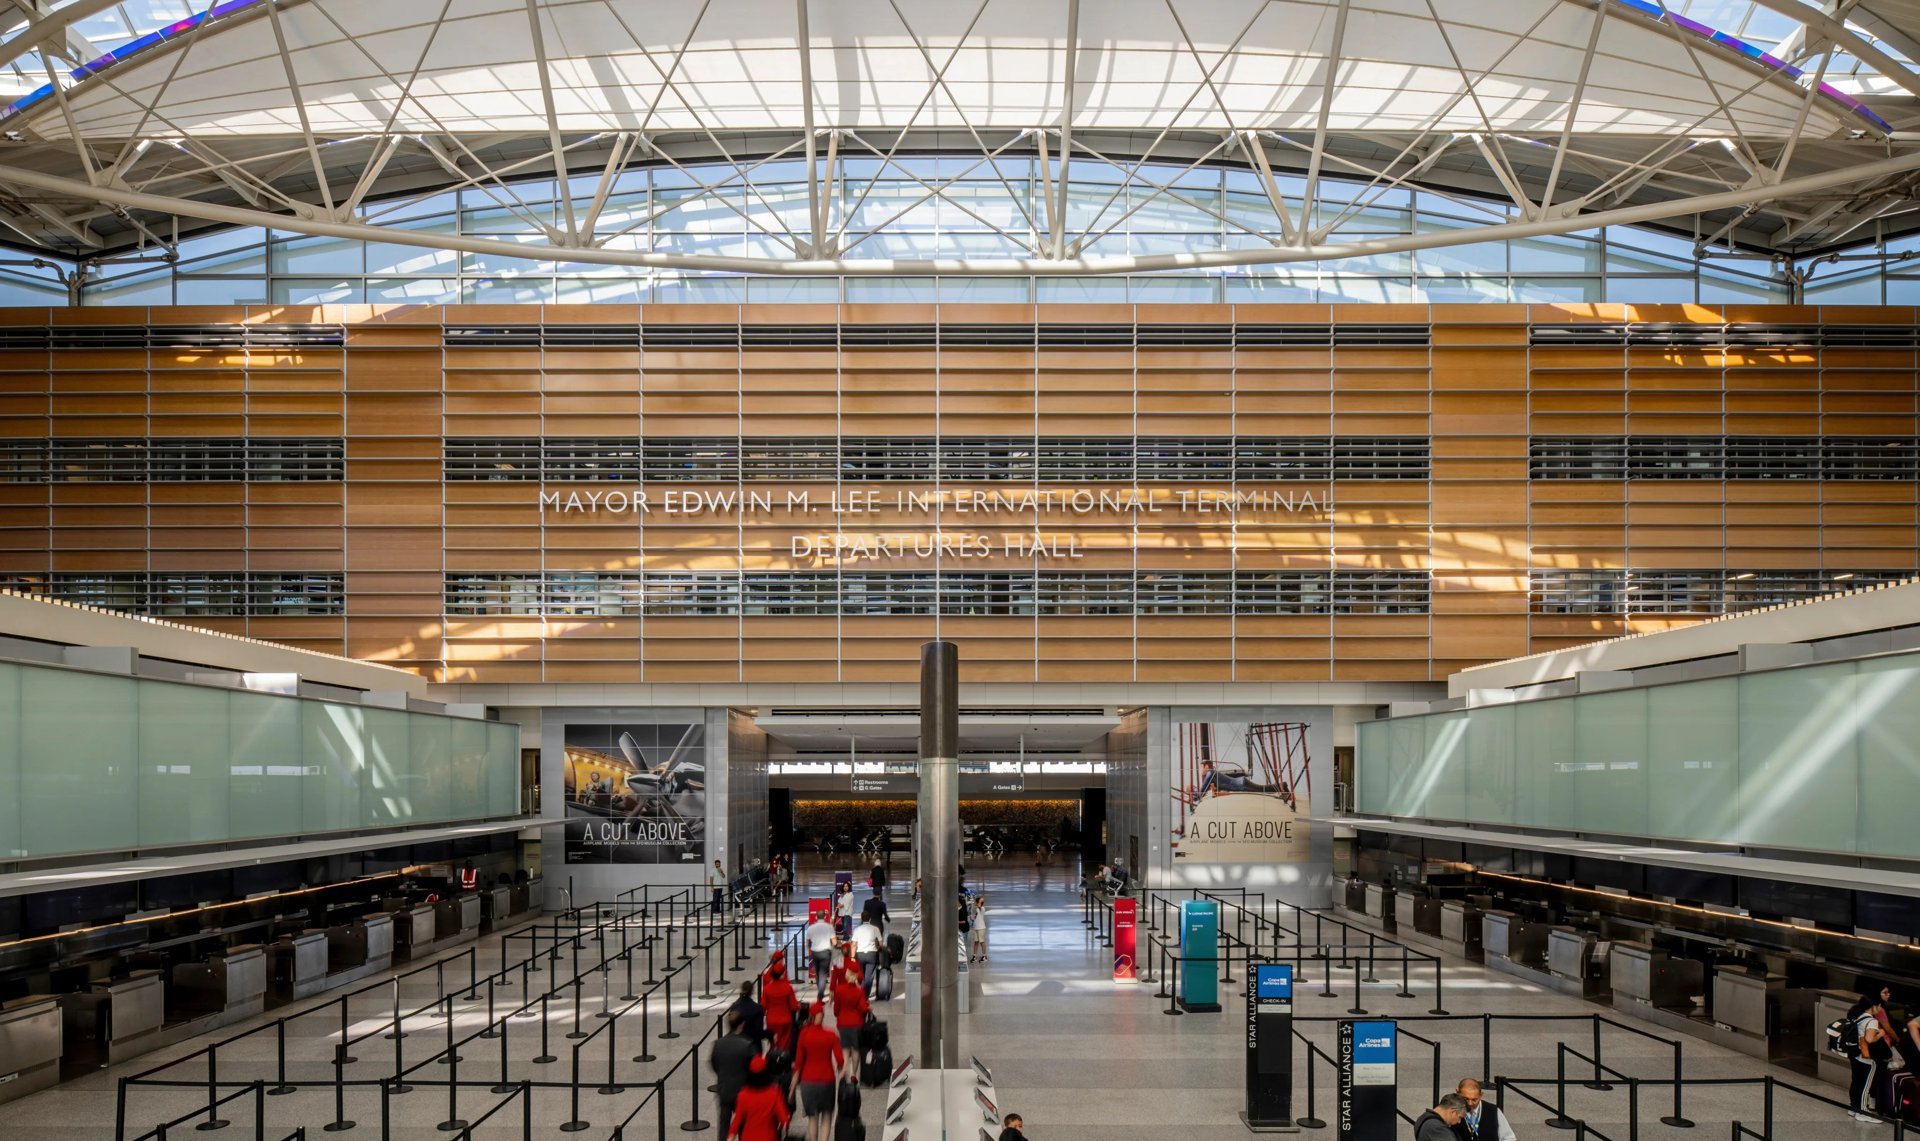
I ended up in the wrong NEXUS line at Vancouver International Airport. By the rules, the mistake was mine. By design, it was an almost predictable wrong turn.
Day twenty-nine of Benchmark Radar. We ranked new releases before routine updates, put a 0 to 1 score on a 0 to 100 scale without changing its value, and made the active tab stay active.
Day twenty-six of Benchmark Radar. We put the ranking where it belongs, made the Back button work, and replaced an invented chart with one we can draw.
When you join a lab, you do not just get a research direction. You inherit a 30-year codebase that is currently running inside the U.S. National Water Model and was on the critical path forecasting Hurricane Harvey. That is what working with Zong-Liang Yang at the Jackson School of Geosciences actually looks like.
Most land surface models treat a tree like a passive straw. Water comes in at the roots, water leaves at the leaves, end of story. Ashley Matheny’s research basically says no, a tree is an active hydraulic system with storage, capacitance, and a strategy, and if you do not model it that way you are going to be wrong about drought.
Most physics undergraduates know Chen Ning Yang as a Nobel laureate and the Y in Yang-Mills. Building him a chronicle made me see something the textbooks gloss over: the most consequential single fact about his life is who his father was, and what that father had set up for him before he was born.
A 1957 Nobel prize cheque, a father who was the first Chinese PhD in number theory, three different monetary regimes, and seventy years of compounding, so how do you put a number on Chen Ning Yang’s family wealth in 2026 without making it up?
A new paper looked at 739 science Nobel laureates from 1901 to 2023, and the headline number that came out is brutal, at the current rate of progress it would take roughly 600 years before a kid born into a poor country has the same shot at a Nobel as a kid born into a rich one.
A new paper looked at 739 science Nobel laureates from 1901 to 2023, and the headline number that came out is brutal, at the current rate of progress it would take roughly 600 years before a kid born into a poor country has the same shot at a Nobel as a kid born into a rich one.
You can study fluid mechanics in five different countries before you turn 30, work on petroleum reservoirs and tectonophysics and planetary ice on the same week, and somehow end up at a Centennial Chair in Geophysics. Marc Hesse did exactly that, and the through-line is more interesting than any of the individual stops.
Day thirty-four of Benchmark Radar. The radar now runs from a command line on your own computer, offline, no dashboard in between, and a coding agent can answer benchmark questions straight from the data. Scoreboard: 121 stars, 23 forks.
Day fifty-six of Benchmark Radar. Contributor winklemad lands two fixes: one makes record-holder credit agree with the record chart, the other keeps every benchmark’s page address unique. Scoreboard: 236 stars, 41 forks.
Day fifty-five of Benchmark Radar. The contributor guide gains one rule: start every branch from an up-to-date main. The WeChat group QR code is refreshed, and the daily scan ran on schedule. Scoreboard: 234 stars, 40 forks.
Day forty of Benchmark Radar. The radar started watching the network where most new benchmark papers get their DOI, brought a benchmark back by searching its exact name, and started posting where it was not posting before. Scoreboard: 147 stars, 27 forks.
Day thirty-nine of Benchmark Radar. The daily brief now has a landing page, a full archive, and a feed of its own, and the dashboard navigation got short enough to scan. Scoreboard: 144 stars, 27 forks.
Day thirty-five of Benchmark Radar. A week-old copycat outranked the real project for its own name because search engines could see only four pages here. Today every one of the 1,173 benchmarks the radar tracks has a page of its own. Scoreboard: 123 stars, 23 forks.
Day thirty-four of Benchmark Radar. The radar now runs from a command line on your own computer, offline, no dashboard in between, and a coding agent can answer benchmark questions straight from the data. Scoreboard: 121 stars, 23 forks.
Day thirty-three of Benchmark Radar. The radar learned to find benchmark releases that keyword search would never catch, and a new frontier model card with 14 benchmarks joined the registry. Scoreboard: 115 stars, 21 forks.
Day thirty-one of Benchmark Radar. Every release card now carries a one-line summary instead of a bare version tag, filing an issue takes at most two required fields, and both READMEs got short enough to read. Scoreboard: 107 stars, 20 forks.
Day thirty of Benchmark Radar. Thirty posts in, this log has become a live broadcast of one open-source project trying to reach 1,000 stars, and today the scoreboard reads 86.
Day forty-four of Benchmark Radar. The paper submodule advances through the citation revision and the source-count revision to the rebuilt PDF. The arXiv submission package assembles. Scoreboard: 175 stars, 31 forks.
You apply to Anthropic, land an offer, then ask HR whether they’ll sponsor your PERM, and they say “on hold for now” or change the subject, and you probably stand there frozen.
Day twenty-seven of Benchmark Radar. We made the Today list load a page at a time, cut a title in half, and taught 21 benchmarks to show their real names.
Day fifty of Benchmark Radar. The paper links point at arXiv everywhere, the README asks readers to upvote on Hugging Face, and a dated laurel badge marks the #1 Paper of the Day on the dashboard. Scoreboard: 185 stars, 30 forks.
Day forty-six of Benchmark Radar. The technical paper is now on arXiv as arXiv:2609.11115, the v0.11.0 release is published with frozen data and verified hashes, and citation surfaces across the project update to the live arXiv entry. Scoreboard: 185 stars, 30 forks.
Day forty-five of Benchmark Radar. The paper enters its final preparation phase: content relicensed to CC BY-NC-SA 4.0, CI checks validate frozen paper data, and report tests align with the manuscript. Scoreboard: 180 stars, 32 forks.
Day forty-four of Benchmark Radar. The paper submodule advances through the citation revision and the source-count revision to the rebuilt PDF. The arXiv submission package assembles. Scoreboard: 175 stars, 31 forks.
Day forty-three of Benchmark Radar. The discovery cutoff for the technical paper locks at 2026-09-07. Source counts, figure data, and the full-catalog audit pipeline freeze for the v0.11.0 release and arXiv submission. Scoreboard: 170 stars, 30 forks.
When you join a lab, you do not just get a research direction. You inherit a 30-year codebase that is currently running inside the U.S. National Water Model and was on the critical path forecasting Hurricane Harvey. That is what working with Zong-Liang Yang at the Jackson School of Geosciences actually looks like.
You can study fluid mechanics in five different countries before you turn 30, work on petroleum reservoirs and tectonophysics and planetary ice on the same week, and somehow end up at a Centennial Chair in Geophysics. Marc Hesse did exactly that, and the through-line is more interesting than any of the individual stops.
If you ask most people where trees in California get their water in a drought, they will say “the soil.” It turns out a huge fraction of it comes from cracks in the bedrock underneath the soil, and Daniella Rempe is the person who put numbers on it.
Most land surface models treat a tree like a passive straw. Water comes in at the roots, water leaves at the leaves, end of story. Ashley Matheny’s research basically says no, a tree is an active hydraulic system with storage, capacitance, and a strategy, and if you do not model it that way you are going to be wrong about drought.
In a field where everyone gets pulled toward the next hot thing, Juan Santiago joined Stanford Mechanical Engineering in 1998 and has been there ever since, building one of the most consequential microfluidics labs on the planet. Long-term focus is its own competitive advantage.
“The laws of physics look the same in every coordinate system” sounds like a platitude, yet Einstein fought over it for eight years and, halfway through, published a proof that it could not be done.
Day fifty-two of Benchmark Radar. The dataset ships to Hugging Face with automated sync, and seventeen project-only words leave the interface for plain language. Scoreboard: 226 stars, 35 forks.
Day forty-nine of Benchmark Radar. The README starts naming its readers: a researchers-by-institution strip with official logos, built by a script, plus a fresh WeChat group code for daily discussion. Scoreboard: 185 stars, 30 forks.
Day forty-eight of Benchmark Radar. The dashboard gets a reader-first pass: the homepage banner keeps its words but drops its pixels, benchmark pages answer what readers actually search for, and an About page tells the project’s story on the site. Scoreboard: 185 stars, 30 forks.
Day forty-seven of Benchmark Radar. With the arXiv paper live, the citation surfaces get a reader-first refresh: the Cite card collapses APA and BibTeX blocks by default, CITATION.md lands in the repo root, and a Cite link joins the top navigation bar. Scoreboard: 185 stars, 30 forks.
Day forty-six of Benchmark Radar. The technical paper is now on arXiv as arXiv:2609.11115, the v0.11.0 release is published with frozen data and verified hashes, and citation surfaces across the project update to the live arXiv entry. Scoreboard: 185 stars, 30 forks.
Day forty-five of Benchmark Radar. The paper enters its final preparation phase: content relicensed to CC BY-NC-SA 4.0, CI checks validate frozen paper data, and report tests align with the manuscript. Scoreboard: 180 stars, 32 forks.
Day forty-four of Benchmark Radar. The paper submodule advances through the citation revision and the source-count revision to the rebuilt PDF. The arXiv submission package assembles. Scoreboard: 175 stars, 31 forks.
Day forty-three of Benchmark Radar. The discovery cutoff for the technical paper locks at 2026-09-07. Source counts, figure data, and the full-catalog audit pipeline freeze for the v0.11.0 release and arXiv submission. Scoreboard: 170 stars, 30 forks.
Day forty-two of Benchmark Radar. The ranking engine for recent releases moves from backend to the dashboard, and the daily radar snapshot captures the first full week of ranked cohorts. Scoreboard: 165 stars, 29 forks.
Day forty-one of Benchmark Radar. The ranking engine for recent releases shipped its first phase with the data contract written first, and the report audit separated raw best scores from scores measured under the same protocol. Scoreboard: 160 stars, 28 forks.
Day forty of Benchmark Radar. The radar started watching the network where most new benchmark papers get their DOI, brought a benchmark back by searching its exact name, and started posting where it was not posting before. Scoreboard: 147 stars, 27 forks.
Day thirty-nine of Benchmark Radar. The daily brief now has a landing page, a full archive, and a feed of its own, and the dashboard navigation got short enough to scan. Scoreboard: 144 stars, 27 forks.
Day thirty-eight of Benchmark Radar. The daily brief, the thing the project already wrote every day and never gave a page, now has a blog and a feed. Scoreboard: 137 stars, 26 forks.
Day thirty-seven of Benchmark Radar. Anyone writing a paper can now copy a citation without leaving the dashboard, the offline setup moved onto the site, and search looks through every collected day by default. Scoreboard: 130 stars, 25 forks.
Day thirty-six of Benchmark Radar. The biggest model card yet landed with 37 scores across 34 benchmarks, and search stopped guessing which result answered the question. Scoreboard: 128 stars, 24 forks.
Day thirty-five of Benchmark Radar. A week-old copycat outranked the real project for its own name because search engines could see only four pages here. Today every one of the 1,173 benchmarks the radar tracks has a page of its own. Scoreboard: 123 stars, 23 forks.
Day thirty-four of Benchmark Radar. The radar now runs from a command line on your own computer, offline, no dashboard in between, and a coding agent can answer benchmark questions straight from the data. Scoreboard: 121 stars, 23 forks.
Day thirty-three of Benchmark Radar. The radar learned to find benchmark releases that keyword search would never catch, and a new frontier model card with 14 benchmarks joined the registry. Scoreboard: 115 stars, 21 forks.
Day thirty-two of Benchmark Radar. We fixed data errors that failed silently, taught the ranking to count adoption for releases that ship no binary files, and rewrote the daily briefing so it reads like a person wrote it. Scoreboard: 113 stars, 21 forks.
Day thirty-one of Benchmark Radar. Every release card now carries a one-line summary instead of a bare version tag, filing an issue takes at most two required fields, and both READMEs got short enough to read. Scoreboard: 107 stars, 20 forks.
Day thirty of Benchmark Radar. Thirty posts in, this log has become a live broadcast of one open-source project trying to reach 1,000 stars, and today the scoreboard reads 86.
Day twenty-six of Benchmark Radar. We put the ranking where it belongs, made the Back button work, and replaced an invented chart with one we can draw.
Day twenty-five of Benchmark Radar. We stopped the radar from ranking itself, put scores on the dates they belong to, and let a benchmark with no score still speak for itself.
“The laws of physics look the same in every coordinate system” sounds like a platitude, yet Einstein fought over it for eight years and, halfway through, published a proof that it could not be done.
Some books leave behind a few ideas. The Mom Test gave me a method I continue to use: do not ask whether someone likes your idea. Ask what they have already done, how often the problem occurs, what it has cost them, and whether they will commit to a next step.
When someone publicly told Steve Jobs that he did not understand technology, Jobs paused, conceded part of the criticism, and asked a more consequential question: what will the customer ultimately gain?
The story goes like this: I’ve been pondering a question lately—given how insanely advanced technology is today, why do we still have to spend so much time dressing up and managing our personal image?
Day forty-nine of Benchmark Radar. The README starts naming its readers: a researchers-by-institution strip with official logos, built by a script, plus a fresh WeChat group code for daily discussion. Scoreboard: 185 stars, 30 forks.
Day forty-two of Benchmark Radar. The ranking engine for recent releases moves from backend to the dashboard, and the daily radar snapshot captures the first full week of ranked cohorts. Scoreboard: 165 stars, 29 forks.
Day forty-one of Benchmark Radar. The ranking engine for recent releases shipped its first phase with the data contract written first, and the report audit separated raw best scores from scores measured under the same protocol. Scoreboard: 160 stars, 28 forks.
Day thirty-two of Benchmark Radar. We fixed data errors that failed silently, taught the ranking to count adoption for releases that ship no binary files, and rewrote the daily briefing so it reads like a person wrote it. Scoreboard: 113 stars, 21 forks.
Day twenty-nine of Benchmark Radar. We ranked new releases before routine updates, put a 0 to 1 score on a 0 to 100 scale without changing its value, and made the active tab stay active.
Does building a benchmark count as research, or is it “crowdfunding a paper”? Does it create public value or consume public resources? Can it build lasting capabilities, or is it useful only for a startup team trying to show investors its potential?
The most dangerous failure mode of an AI science benchmark is not that it is too hard, it is that it quietly becomes either a coding trick or a guessing game.
Day forty-six of Benchmark Radar. The technical paper is now on arXiv as arXiv:2609.11115, the v0.11.0 release is published with frozen data and verified hashes, and citation surfaces across the project update to the live arXiv entry. Scoreboard: 185 stars, 30 forks.
When someone publicly told Steve Jobs that he did not understand technology, Jobs paused, conceded part of the criticism, and asked a more consequential question: what will the customer ultimately gain?
Does building a benchmark count as research, or is it “crowdfunding a paper”? Does it create public value or consume public resources? Can it build lasting capabilities, or is it useful only for a startup team trying to show investors its potential?
A new paper looked at 739 science Nobel laureates from 1901 to 2023, and the headline number that came out is brutal, at the current rate of progress it would take roughly 600 years before a kid born into a poor country has the same shot at a Nobel as a kid born into a rich one.
Anthropic’s most ruthless move isn’t polishing every product to perfection before release, but daring to throw out a research preview first, then rapidly getting stronger in front of everyone.
A 1957 Nobel prize cheque, a father who was the first Chinese PhD in number theory, three different monetary regimes, and seventy years of compounding, so how do you put a number on Chen Ning Yang’s family wealth in 2026 without making it up?
Day forty-eight of Benchmark Radar. The dashboard gets a reader-first pass: the homepage banner keeps its words but drops its pixels, benchmark pages answer what readers actually search for, and an About page tells the project’s story on the site. Scoreboard: 185 stars, 30 forks.
Day thirty-eight of Benchmark Radar. The daily brief, the thing the project already wrote every day and never gave a page, now has a blog and a feed. Scoreboard: 137 stars, 26 forks.
Day thirty-five of Benchmark Radar. A week-old copycat outranked the real project for its own name because search engines could see only four pages here. Today every one of the 1,173 benchmarks the radar tracks has a page of its own. Scoreboard: 123 stars, 23 forks.
Day twenty-seven of Benchmark Radar. We made the Today list load a page at a time, cut a title in half, and taught 21 benchmarks to show their real names.
Day twenty-nine of Benchmark Radar. We ranked new releases before routine updates, put a 0 to 1 score on a 0 to 100 scale without changing its value, and made the active tab stay active.
Does building a benchmark count as research, or is it “crowdfunding a paper”? Does it create public value or consume public resources? Can it build lasting capabilities, or is it useful only for a startup team trying to show investors its potential?
The most dangerous failure mode of an AI science benchmark is not that it is too hard, it is that it quietly becomes either a coding trick or a guessing game.
A 1957 Nobel prize cheque, a father who was the first Chinese PhD in number theory, three different monetary regimes, and seventy years of compounding, so how do you put a number on Chen Ning Yang’s family wealth in 2026 without making it up?
A new paper looked at 739 science Nobel laureates from 1901 to 2023, and the headline number that came out is brutal, at the current rate of progress it would take roughly 600 years before a kid born into a poor country has the same shot at a Nobel as a kid born into a rich one.
Day twenty-five of Benchmark Radar. We stopped the radar from ranking itself, put scores on the dates they belong to, and let a benchmark with no score still speak for itself.
Day thirty-seven of Benchmark Radar. Anyone writing a paper can now copy a citation without leaving the dashboard, the offline setup moved onto the site, and search looks through every collected day by default. Scoreboard: 130 stars, 25 forks.
Day thirty-six of Benchmark Radar. The biggest model card yet landed with 37 scores across 34 benchmarks, and search stopped guessing which result answered the question. Scoreboard: 128 stars, 24 forks.
I was in the middle of setting up a second Cloudflare backup, verifying one dataset and configuring another, when the AI agent helping me flagged something unrelated: while listing what had access to my GitHub account, one authorization stood out as unusually broad. That single flag turned into an hour of reviewing GitHub’s installed-apps list, and it was worth every minute.
A receipt in Singapore showed S$5.50, while a U.S. credit-card account displayed only US$4.27. Another purchase of about S$48 appeared as roughly US$38. A bank-card transit ride also failed to appear immediately as pending.
Day forty of Benchmark Radar. The radar started watching the network where most new benchmark papers get their DOI, brought a benchmark back by searching its exact name, and started posting where it was not posting before. Scoreboard: 147 stars, 27 forks.
A 1957 Nobel prize cheque, a father who was the first Chinese PhD in number theory, three different monetary regimes, and seventy years of compounding, so how do you put a number on Chen Ning Yang’s family wealth in 2026 without making it up?
In a field where everyone gets pulled toward the next hot thing, Juan Santiago joined Stanford Mechanical Engineering in 1998 and has been there ever since, building one of the most consequential microfluidics labs on the planet. Long-term focus is its own competitive advantage.
Some books leave behind a few ideas. The Mom Test gave me a method I continue to use: do not ask whether someone likes your idea. Ask what they have already done, how often the problem occurs, what it has cost them, and whether they will commit to a next step.
When someone publicly told Steve Jobs that he did not understand technology, Jobs paused, conceded part of the criticism, and asked a more consequential question: what will the customer ultimately gain?
Some books leave behind a few ideas. The Mom Test gave me a method I continue to use: do not ask whether someone likes your idea. Ask what they have already done, how often the problem occurs, what it has cost them, and whether they will commit to a next step.
I spent the last couple of days checking a tempting claim: that Microsoft Flight Simulator is secretly the foundation for a broader Earth digital twin story.
Some books leave behind a few ideas. The Mom Test gave me a method I continue to use: do not ask whether someone likes your idea. Ask what they have already done, how often the problem occurs, what it has cost them, and whether they will commit to a next step.
The story goes like this: I’ve been pondering a question lately—given how insanely advanced technology is today, why do we still have to spend so much time dressing up and managing our personal image?
Day twenty-seven of Benchmark Radar. We made the Today list load a page at a time, cut a title in half, and taught 21 benchmarks to show their real names.
I ran a health check on my Claude Code setup this week and found 174 custom skills, 124 of which I had never invoked once. They were not failures. Most of them were scaffolding I built for a model that needed it, and then kept long after the model stopped needing it.
Most physics undergraduates know Chen Ning Yang as a Nobel laureate and the Y in Yang-Mills. Building him a chronicle made me see something the textbooks gloss over: the most consequential single fact about his life is who his father was, and what that father had set up for him before he was born.
Day forty-two of Benchmark Radar. The ranking engine for recent releases moves from backend to the dashboard, and the daily radar snapshot captures the first full week of ranked cohorts. Scoreboard: 165 stars, 29 forks.
Most physics undergraduates know Chen Ning Yang as a Nobel laureate and the Y in Yang-Mills. Building him a chronicle made me see something the textbooks gloss over: the most consequential single fact about his life is who his father was, and what that father had set up for him before he was born.
One hundred twenty-six thousand eight hundred and eighty-seven dollars is housing-level money in Austin; in UT Austin’s new business-school building, it buys a single parking spot.
When you join a lab, you do not just get a research direction. You inherit a 30-year codebase that is currently running inside the U.S. National Water Model and was on the critical path forecasting Hurricane Harvey. That is what working with Zong-Liang Yang at the Jackson School of Geosciences actually looks like.
You can study fluid mechanics in five different countries before you turn 30, work on petroleum reservoirs and tectonophysics and planetary ice on the same week, and somehow end up at a Centennial Chair in Geophysics. Marc Hesse did exactly that, and the through-line is more interesting than any of the individual stops.
The same way text foundation models ate NLP and image models ate computer vision, someone is going to build the foundation model that eats spatial reasoning. Gengchen Mai is one of the people taking that bet seriously, and his SEAI Lab at UT Austin is one of the places it is being built.
Most academic climate scientists will tell you they care about policy and then publish a paper that no policymaker is ever going to read. Geeta Persad spent four years working at the Union of Concerned Scientists translating climate models for water managers, and she came back to academia knowing exactly what the gap looks like.
If you ask most people where trees in California get their water in a drought, they will say “the soil.” It turns out a huge fraction of it comes from cracks in the bedrock underneath the soil, and Daniella Rempe is the person who put numbers on it.
Most land surface models treat a tree like a passive straw. Water comes in at the roots, water leaves at the leaves, end of story. Ashley Matheny’s research basically says no, a tree is an active hydraulic system with storage, capacitance, and a strategy, and if you do not model it that way you are going to be wrong about drought.
Day forty-eight of Benchmark Radar. The dashboard gets a reader-first pass: the homepage banner keeps its words but drops its pixels, benchmark pages answer what readers actually search for, and an About page tells the project’s story on the site. Scoreboard: 185 stars, 30 forks.
Day forty-seven of Benchmark Radar. With the arXiv paper live, the citation surfaces get a reader-first refresh: the Cite card collapses APA and BibTeX blocks by default, CITATION.md lands in the repo root, and a Cite link joins the top navigation bar. Scoreboard: 185 stars, 30 forks.
A street vendor earns a markup. A person who builds a company earns a valuation. Between the two sits one question: who gets other people’s money first.
A street vendor earns a markup. A person who builds a company earns a valuation. Between the two sits one question: who gets other people’s money first.
Day seven was the biggest single day. Hi, Koutian here. We launched a new leaderboard, grew the registry to the 2026 frontier, and bumped the version to 0.3.0.
A 1957 Nobel prize cheque, a father who was the first Chinese PhD in number theory, three different monetary regimes, and seventy years of compounding, so how do you put a number on Chen Ning Yang’s family wealth in 2026 without making it up?
A new paper looked at 739 science Nobel laureates from 1901 to 2023, and the headline number that came out is brutal, at the current rate of progress it would take roughly 600 years before a kid born into a poor country has the same shot at a Nobel as a kid born into a rich one.
Most enterprise security companies show up, ride one trend, and disappear in the next infrastructure cycle. Sean Xiang has been building Bloombase since January 2012, and the company has somehow been on the right side of every major infrastructure shift since, including the current AI accelerator era. That is not luck. That is a thesis.
Most VCs and accelerators talk about supporting founders. Kehan Dong specifically supports the kind of founder who started building at 16, when nobody told them they were allowed to, and it turns out that population is dramatically underserved.
Rereading my old journals today, from nuclear fusion in physics to the games humans play, I keep finding the same thing. Whether it is a startup or a whole industry, what matters is a force that rises on its own and then keeps itself going.
I ended up in the wrong NEXUS line at Vancouver International Airport. By the rules, the mistake was mine. By design, it was an almost predictable wrong turn.
Beyond the wayfinding problem that led me into the wrong NEXUS line, my connection at Vancouver International Airport left me with several observations unrelated to signs. I noticed an older-looking mix of people, a departures area that offered almost nowhere to work, and a visible contrast between people in Vancouver and Texas. This post records those observations. The full account of the NEXUS incident is in How I “Reasonably” Ended Up in the Wrong NEXUS Line at YVR.
A 1957 Nobel prize cheque, a father who was the first Chinese PhD in number theory, three different monetary regimes, and seventy years of compounding, so how do you put a number on Chen Ning Yang’s family wealth in 2026 without making it up?
Most physics undergraduates know Chen Ning Yang as a Nobel laureate and the Y in Yang-Mills. Building him a chronicle made me see something the textbooks gloss over: the most consequential single fact about his life is who his father was, and what that father had set up for him before he was born.
When you go looking for a seat in the great theater of the AI era, built from PowerPoints, papers, and anxiety, it helps to look at which play each person on stage is performing.
On a stormy Sunday afternoon in 1988, Edmund Clarke, a Carnegie Mellon professor and Turing Award winner, came to lecture at Fudan University and found the room nearly empty.
When an AI writing assistant turns a paper’s incoherent rambling into a “well-structured pile of something,” we have to admit: it is basically a cyber laxative.
Most physics undergraduates know Chen Ning Yang as a Nobel laureate and the Y in Yang-Mills. Building him a chronicle made me see something the textbooks gloss over: the most consequential single fact about his life is who his father was, and what that father had set up for him before he was born.
On a stormy Sunday afternoon in 1988, Edmund Clarke, a Carnegie Mellon professor and Turing Award winner, came to lecture at Fudan University and found the room nearly empty.
Today I had an interesting experience collaborating with Claude Code to completely overhaul my personal academic website. As a PhD student in Geological and Earth Sciences at UT Austin, I needed to update my GitHub Pages site with real professional information instead of the placeholder content that had been sitting there.
Most academic climate scientists will tell you they care about policy and then publish a paper that no policymaker is ever going to read. Geeta Persad spent four years working at the Union of Concerned Scientists translating climate models for water managers, and she came back to academia knowing exactly what the gap looks like.
The sense of agency that took me more than twenty years to grow, these seventeen and eighteen year old students got far more easily, just by being at Stanford, being in America, or maybe going to high school in Shanghai first.
At today’s Silicon Valley alumni “Ask a Question” AI meet-up, what I wanted to talk about wasn’t how cool Claude Code is, but how it actually re-slices real work.
The signal truly worth heeding is not that AI companies are growing too slowly, but that they are growing fast while cash-flow pressure keeps mounting.
If you’ve been watching the business map of the AI track lately, you can’t help but be shaken by that trend feverishly racing from “human-machine collaboration” toward “multi-agent autonomy.”
I asked Claude Code a narrow question: can I protect this machine from Codex accidentally deleting files forever, just by aliasing rm to trash? The honest answer turned out to be no, for a reason that is not obvious until you actually test it, and the fix ended up being a five-layer setup rather than a one-liner.
Parameterizing a large Fortran climate model by hand is slow, error-prone, and hard to validate. Noah-Agent asks whether a team of specialized AI agents can do it instead.
The Tmux Orchestrator enables Claude agents to work autonomously, schedule their own check-ins, and coordinate across multiple projects without human intervention - a project I explored and learned a lot from.
If I reopened the 2026 folder in 2030, I would check one thing first: did the work completed with AI change a real problem and leave evidence that others could verify and build upon?
Recently I’ve sometimes felt confused by how far AI has come, a bit lost and anxious, unsure what I should do, and then, because of my identity and my path, wondering what fallbacks or better options exist.
Many Chinese teams building embodied AI or AI applications hit the same real-world problem: the domestic models aren’t enough, and they want to call the APIs of foreign models like OpenAI and Anthropic directly. That’s why a swarm of “relay,” “recharge,” and “one OpenAI-compatible interface for you” businesses has sprung up.
I am deeply honored to join my colleagues in contributing to the newly published paper, “On the Ethics of Generative GeoAI: Explainability, Bias, Hallucination, Accountability, Privacy, and Trust,” specifically focusing on the section regarding GeoAI Trust (Section 8).
Earlier today I published a piece called “Four Ego Mistakes I Made as a 22-Year-Old Founder.” Then I ran it through Gemini 2.5 Pro as an independent reviewer. Gemini’s verdict was that the essay is itself an ego move. I think Gemini is mostly right.
Call it a (10^5) gap if you like, once you put semantic entropy and effective training samples on the board, the difference between internet-scale text and embodied robotics data stops sounding like rhetorical inflation and starts sounding almost conservative. You just have to separate raw physics bits from semantics a learner can actually use.
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
Top physics researchers aren’t blind to what AI is doing in the application layer. They’re locked by their own evaluation system and can’t afford to look.
A PhD is hard. A PhD in 2026 — with the field moving faster than your committee can read — is a different kind of hard. AI PhD Survival Guide is a handbook for surviving and finishing an AI or ML PhD without burning out and without falling behind.
Virtual cell models powered by neuromorphic computing and gene language models represent one of the most capital-intensive and scientifically ambitious convergences in biotech AI. If you’re evaluating this space as a VC intern, you need to understand three core components: what these systems actually do, why the market is moving now, and where the investable opportunities lie.
Research, stock trading, and startups all share a common pattern: success comes from combining a defensible core competency with the ability to ride trending waves. You don’t need exhaustive preparation anymore. You need methodology and the ability to produce content when it matters. When the right moment arrives, you strike.
When Large Language Models (LLMs) hallucinate, we often treat it as an engineering bug to be fixed. But what if hallucinations are not a flaw, but a mathematical inevitability? A recent interdisciplinary discussion revealed a profound connection between the Gibbs phenomenon in Fourier analysis and the fundamental limitations of neural networks.
How photographing a black hole and training GPT-4 are fundamentally the same process: extracting coherent structure from impossibly sparse frequency-domain measurements.
The promise of AI-automated science is intoxicating: imagine machines that can generate hypotheses, design experiments, and publish papers while we sleep.
I’ve been discussing this question with a friend lately. He wants to use AI for matching in the dating market; I think with a small sample size this is perfectly feasible, you don’t even need to build any search/ads/rec system at all. Just ask the large language model directly, toss in a few users’ profiles, and have it rank them; the whole process is very simple.
The signal truly worth heeding is not that AI companies are growing too slowly, but that they are growing fast while cash-flow pressure keeps mounting.
Every knowledge worker is now competing with an LLM for some part of their job. AI Survival Guide is a handbook for figuring out which parts, what to do about it, and how to come out the other side better at your craft instead of replaced by it.
If you’ve been watching the business map of the AI track lately, you can’t help but be shaken by that trend feverishly racing from “human-machine collaboration” toward “multi-agent autonomy.”
Sometimes a piece of old science fiction stays in your head not because of the gadgets, but because it got the emotional structure of the future right.
Every generation has its own way of managing work: paper notebooks, SaaS task managers, and now programmable agentic workflows powered by tools like OpenClaw heartbeat.
Lay out every hyped multiAgent product on a table in front of Steve Jobs and he would probably squint, frown, and ask one question, why on earth are you showing the user any of this.
To be totally honest with you, you don’t need to understand the underlying architecture of large language models to get your name on a top-tier AI paper right now, you just need to be a true expert in your own field.
If you’re serious about understanding LLMs and AI engineering, Simon Willison’s Newsletter is one of the best resources out there. With over 38,000 subscribers, it provides detailed analysis on AI, LLMs, web engineering, open source, data science, and Python.
Parameterizing a large Fortran climate model by hand is slow, error-prone, and hard to validate. Noah-Agent asks whether a team of specialized AI agents can do it instead.
A hand-controlled 3D visualization of your AI conversation history - fly through ChatGPT conversations and explore artificial intelligence concepts. Try Live Demo
Most crypto dashboards either drown you in numbers or hide the signal behind a paywall. Crypto Dashboard is my attempt at a clean, AI-augmented view of the market that runs entirely in your browser. Try Live Demo
AlphaEarthHack is the project our team built for the UT Austin Geoscience Hackathon. The goal: see how far we could push AI on Earth system data inside a single weekend. Try Live Demo
The Tmux Orchestrator enables Claude agents to work autonomously, schedule their own check-ins, and coordinate across multiple projects without human intervention - a project I explored and learned a lot from.
Yuxuan and I have been discussing AI agent ideas for a while. Yesterday, we finally decided: we’re building Atomize, a task-breaking agent system evolved from Goblin Tools.
Decades of Earth-system modeling judgment live in PDFs, mailing lists, and senior researchers’ heads, and none of it is loadable by an AI coding agent. earth-space-ai.org is an attempt to fix that.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
Port Aransas South Jetty published an Institute Insights feature on May 28, 2026 about how our University of Texas team is using satellite remote sensing and AI to monitor Texas coastal water quality.
A bit of history from a casual chat: in the US, science students used to get bigger stipends than business, law or medicine students, because science students were poor.
Today I had an interesting experience collaborating with Claude Code to completely overhaul my personal academic website. As a PhD student in Geological and Earth Sciences at UT Austin, I needed to update my GitHub Pages site with real professional information instead of the placeholder content that had been sitting there.
The promise of AI-automated science is intoxicating: imagine machines that can generate hypotheses, design experiments, and publish papers while we sleep.
Call it a (10^5) gap if you like, once you put semantic entropy and effective training samples on the board, the difference between internet-scale text and embodied robotics data stops sounding like rhetorical inflation and starts sounding almost conservative. You just have to separate raw physics bits from semantics a learner can actually use.
Exchanging money for time is a privilege I rarely indulge in, but a surprise membership benefit that cleared airport security in ten minutes changed my perspective on friction and market regulation. While a Clear Plus membership normally costs over a hundred dollars annually, obtaining it for free through an Uber membership allowed me to experience a level of efficiency that money can’t always buy—at least not without a well-regulated system behind it.
I ended up in the wrong NEXUS line at Vancouver International Airport. By the rules, the mistake was mine. By design, it was an almost predictable wrong turn.
Beyond the wayfinding problem that led me into the wrong NEXUS line, my connection at Vancouver International Airport left me with several observations unrelated to signs. I noticed an older-looking mix of people, a departures area that offered almost nowhere to work, and a visible contrast between people in Vancouver and Texas. This post records those observations. The full account of the NEXUS incident is in How I “Reasonably” Ended Up in the Wrong NEXUS Line at YVR.
alphaXiv hosts a discussion page for our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation, with the abstract, author list, BibTeX citation, and open discussion.
At the Metropolitan Museum of Art in New York, I walked into a real ancient Egyptian tomb, not a replica or a model, but a tomb that stood in the Egyptian desert more than four thousand years ago and was moved whole to Manhattan.
Every indie developer who has ever burned through a free API tier knows the feeling: you build something cool, and then your OPENAI_API_KEY runs out at the worst possible moment. hao-tokens is a curated list of the legitimate ways to get free or low-cost LLM tokens so you can keep building.
Every indie developer who has ever burned through a free API tier knows the feeling: you build something cool, and then your OPENAI_API_KEY runs out at the worst possible moment. hao-tokens is a curated list of the legitimate ways to get free or low-cost LLM tokens so you can keep building.
Day fifty of Benchmark Radar. The paper links point at arXiv everywhere, the README asks readers to upvote on Hugging Face, and a dated laurel badge marks the #1 Paper of the Day on the dashboard. Scoreboard: 185 stars, 30 forks.
Day forty-six of Benchmark Radar. The technical paper is now on arXiv as arXiv:2609.11115, the v0.11.0 release is published with frozen data and verified hashes, and citation surfaces across the project update to the live arXiv entry. Scoreboard: 185 stars, 30 forks.
The thing that almost stranded me on this international trip was not a typhoon, but several unrelated systems deciding at the same time that they did not trust me.
NASA’s Future Investigators in NASA Earth and Space Science and Technology (FINESST) is one of the most underused fellowships among US graduate students. Most PhD students have never heard of it, and the ones who have often miss the deadline because the proposal expectations aren’t obvious from the call alone. This repo is a curated guide of links, tips, and examples to help you write a competitive FINESST proposal.
The thing that almost stranded me on this international trip was not a typhoon, but several unrelated systems deciding at the same time that they did not trust me.
Today I had an interesting experience collaborating with Claude Code to completely overhaul my personal academic website. As a PhD student in Geological and Earth Sciences at UT Austin, I needed to update my GitHub Pages site with real professional information instead of the placeholder content that had been sitting there.
The Tmux Orchestrator enables Claude agents to work autonomously, schedule their own check-ins, and coordinate across multiple projects without human intervention - a project I explored and learned a lot from.
USTC recognized my project with the 2023 Undergraduate Research Plan Outstanding Award. The project used WACCM-X and observations to study how the 2022 Tonga eruption disturbed the mesosphere and lower thermosphere.
USTC awarded my undergraduate thesis a 2024 Outstanding Graduation Thesis Award. The thesis studied the 2022 Tonga volcanic eruption’s disturbance of the mesosphere and lower thermosphere using WACCM-X simulations and observations.
As we walked out of the library, an elderly white woman with silver hair saw us and said “excuse me” three times. She spoke to us with real pride, took out her phone, and said she had seen the two of us taking photos with the frog statue out front. Every Christmas, she told us, that frog gets dressed up in a Christmas outfit, look, just like this! Then she asked, very sincerely, whether we would still be here at Christmas, and how we had even heard of Atherton, because the place is so unremarkable, so quiet, so low-key. We told her we would probably each be heading home by then. She added that her son had been learning Chinese since he was a little kid, and that he speaks it really well.
If you ask most people where trees in California get their water in a drought, they will say “the soil.” It turns out a huge fraction of it comes from cracks in the bedrock underneath the soil, and Daniella Rempe is the person who put numbers on it.
I submitted our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation to Hugging Face Daily Papers on September 14, 2026, and readers voted it to the top of that day’s list. As of September 29 it has 171 upvotes, the most of the 26 papers posted that day.
2026 年 9 月 14 日,我把论文 Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation 提交到 Hugging Face Daily Papers,读者把它投上了当天榜首。截至 9 月 29 日,它获得 171 个赞,在当天 26 篇论文中排第一。
The Isfahan AI Desk (میز هوش مصنوعی استان اصفهان), the province’s AI governance and ecosystem watch, listed our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation (arXiv:2609.11115) in its news radar with a relevance score of 91/100.
伊斯法罕省 AI 治理与生态观察(میز هوش مصنوعی استان اصفهان)把我们的论文 Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation(arXiv:2609.11115)列入新闻雷达,相关度评分 91/100。
Strongly Typed AI News, the AI news site Alexy Khrabrov runs at collected.ga, made our paper the lead story of its September 12, 2026 “Typesafe AI Daily” issue. Its crawler checked 49 sources that day and found 12 strong signals across AI infrastructure, funding, research, and developer tools, and it named Benchmark Radar the strongest of them.
Papers with Code listed our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation (arXiv:2609.11115), with its TL;DR, abstract, code repository, and project page.
Moonlight, the AI research-reading companion by Corca, published a literature-review page for our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation.
Geepity turned our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation into a full interactive reading edition, walking through all nine chapters with live charts and a working BM25F demo.
DailyAIWire covered the Benchmark Radar launch as a centralized AI evaluation database, with an AI-assisted intelligence report, an explain-like-I’m-five summary, and a visual flow of the system.
arXivDaily, the Chinese arXiv digest with per-university pages, lists our paper on its Shanghai Jiao Tong University page, following the SJTU affiliation on the author list.
alphaXiv hosts a discussion page for our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation, with the abstract, author list, BibTeX citation, and open discussion.
Most of biology is averages. You measure a million cells, you get a mean. Eric Greene’s lab figured out how to actually watch one DNA molecule at a time, repair itself, in real time, and that changes what kind of questions biology can ask.
Virtual cell models powered by neuromorphic computing and gene language models represent one of the most capital-intensive and scientifically ambitious convergences in biotech AI. If you’re evaluating this space as a VC intern, you need to understand three core components: what these systems actually do, why the market is moving now, and where the investable opportunities lie.
Most crypto dashboards either drown you in numbers or hide the signal behind a paywall. Crypto Dashboard is my attempt at a clean, AI-augmented view of the market that runs entirely in your browser. Try Live Demo
Sometimes a piece of old science fiction stays in your head not because of the gadgets, but because it got the emotional structure of the future right.
If you’ve been watching the business map of the AI track lately, you can’t help but be shaken by that trend feverishly racing from “human-machine collaboration” toward “multi-agent autonomy.”
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
Most people think of summer vacation as time off. I started wondering whether that framing undersells it. Summer Calculator is a small web tool that estimates the full value of your summer — money, learning, relationships, health — not just the days you didn’t work. Try Live Demo
School rankings are a single number standing in for a multi-dimensional decision. School Evaluator is a small web tool that lets you score a school across the dimensions that actually shape your life there. Try Live Demo
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
Recently I’ve sometimes felt confused by how far AI has come, a bit lost and anxious, unsure what I should do, and then, because of my identity and my path, wondering what fallbacks or better options exist.
Top physics researchers aren’t blind to what AI is doing in the application layer. They’re locked by their own evaluation system and can’t afford to look.
Research, stock trading, and startups all share a common pattern: success comes from combining a defensible core competency with the ability to ride trending waves. You don’t need exhaustive preparation anymore. You need methodology and the ability to produce content when it matters. When the right moment arrives, you strike.
Every knowledge worker is now competing with an LLM for some part of their job. AI Survival Guide is a handbook for figuring out which parts, what to do about it, and how to come out the other side better at your craft instead of replaced by it.
Every generation has its own way of managing work: paper notebooks, SaaS task managers, and now programmable agentic workflows powered by tools like OpenClaw heartbeat.
To be totally honest with you, you don’t need to understand the underlying architecture of large language models to get your name on a top-tier AI paper right now, you just need to be a true expert in your own field.
In October 2023 I asked ChatGPT an over-engineered question: how do you fry rice so that every grain of rice ends up bonded to egg, with no bare rice grains and no isolated clumps of egg sitting off on their own? I saved that conversation as an HTML file, dropped it in my Downloads folder, and did not look at it again for almost three years. Last week I finally turned it into an actual open-source repo, and going back through the original conversation to build it was more interesting than I expected.
“这b人生过的值不值” — roughly, “was this damn life worth it?” — is a phrase that does a lot of emotional work on the Chinese internet. ZuoGuoHuaDiao (做过划掉) is a small web tool that takes the phrase seriously and tries to answer it with numbers. Try Live Demo
The US is full of small traps that nobody warns you about until after you’ve fallen into one. US Survival Guide is a handbook for Chinese students and newcomers on identifying risk early, knowing your rights, and building a financial defense before you need it. Read the Guide
Most physics undergraduates know Chen Ning Yang as a Nobel laureate and the Y in Yang-Mills. Building him a chronicle made me see something the textbooks gloss over: the most consequential single fact about his life is who his father was, and what that father had set up for him before he was born.
Every indie developer who has ever burned through a free API tier knows the feeling: you build something cool, and then your OPENAI_API_KEY runs out at the worst possible moment. hao-tokens is a curated list of the legitimate ways to get free or low-cost LLM tokens so you can keep building.
I asked Claude Code a narrow question: can I protect this machine from Codex accidentally deleting files forever, just by aliasing rm to trash? The honest answer turned out to be no, for a reason that is not obvious until you actually test it, and the fix ended up being a five-layer setup rather than a one-liner.
When you join a lab, you do not just get a research direction. You inherit a 30-year codebase that is currently running inside the U.S. National Water Model and was on the critical path forecasting Hurricane Harvey. That is what working with Zong-Liang Yang at the Jackson School of Geosciences actually looks like.
AlphaEarthHack is the project our team built for the UT Austin Geoscience Hackathon. The goal: see how far we could push AI on Earth system data inside a single weekend. Try Live Demo
Dr. Zong-Liang Yang’s Land Environment and Atmospheric Dynamics (LEAD) Group at UT-Austin employs satellite remote sensing, earth system modeling, and high-performance computing to advance understanding of Earth system sciences.
Most academic climate scientists will tell you they care about policy and then publish a paper that no policymaker is ever going to read. Geeta Persad spent four years working at the Union of Concerned Scientists translating climate models for water managers, and she came back to academia knowing exactly what the gap looks like.
Most academic climate scientists will tell you they care about policy and then publish a paper that no policymaker is ever going to read. Geeta Persad spent four years working at the Union of Concerned Scientists translating climate models for water managers, and she came back to academia knowing exactly what the gap looks like.
Decades of Earth-system modeling judgment live in PDFs, mailing lists, and senior researchers’ heads, and none of it is loadable by an AI coding agent. earth-space-ai.org is an attempt to fix that.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
Parameterizing a large Fortran climate model by hand is slow, error-prone, and hard to validate. Noah-Agent asks whether a team of specialized AI agents can do it instead.
The roar of cooling systems in the Texas Advanced Computing Center (TACC) isn’t just noise—it’s the power of supercomputers translating the overwhelming dimensionality of climate data into something students can finally see and understand.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
I asked Claude Code a narrow question: can I protect this machine from Codex accidentally deleting files forever, just by aliasing rm to trash? The honest answer turned out to be no, for a reason that is not obvious until you actually test it, and the fix ended up being a five-layer setup rather than a one-liner.
School rankings are a single number standing in for a multi-dimensional decision. School Evaluator is a small web tool that lets you score a school across the dimensions that actually shape your life there. Try Live Demo
A widely shared post describes a brainstorming meeting at a robotics startup in Boston. A slide said “No stupid questions.” A Chinese employee interpreted it as “Do not ask stupid questions,” while American colleagues explained it as “Ask freely; no question will be judged stupid.” A related post claims that “Say it again?” is neutral when someone is not heard, whereas “What did you say?” is hostile.
一张流传截图讲了这样一件事:一家波士顿机器人创业公司开头脑风暴会,幻灯片写着 “No stupid questions.” 一位中国员工把它理解为“不要问蠢问题”,美国同事却说它的意思是“什么都可以问,没有问题会被当成蠢问题”。另一组讨论又声称:没听清时说 “Say it again?” 很中性,而 “What did you say?” 很不友好。
The USTC Student Club Association recorded the founding of the Xingyun Poetry Club, which I helped start. The club created a home for poetry readings, writing, and student-run cultural events; its activities and posts later reached more than 100,000 views across platforms.
瀚海奇点 covered USTC’s 2021 Science Fiction Night. I took part in the event, which brought students together around science fiction, ideas, and creative work.
Starting a petition, founding a club, and joining a research effort someone else organized look like three different things. They all run into the same question: who decides, who puts in the time, and when something goes wrong, who bears the consequences?
Rereading my old journals today, from nuclear fusion in physics to the games humans play, I keep finding the same thing. Whether it is a startup or a whole industry, what matters is a force that rises on its own and then keeps itself going.
Many Chinese teams building embodied AI or AI applications hit the same real-world problem: the domestic models aren’t enough, and they want to call the APIs of foreign models like OpenAI and Anthropic directly. That’s why a swarm of “relay,” “recharge,” and “one OpenAI-compatible interface for you” businesses has sprung up.
People love saying that ten years to a billion-dollar valuation is the normal pace for a unicorn, neither fast nor slow. But once you actually crunch the compound numbers, you realize what hides behind that word “normal” is a beast that doubles in value every single year.
Don’t expect your first video to go viral, and don’t expect your first sales trip to land ten million dollars, but you can ask what happens after the hundredth try.
The talk that stayed with me at the Texas Symposium on Machine Learning, Responsible AI & Robotics 2026 was about extending language models, not just making them bigger.
In my first post on this I described sending a patch through GitGitGadget and watching it land on the mailing list as v1. That post ended with the patch waiting for review. It has since merged. Now that I have seen the full lifecycle, from typo to master, here is what actually mattered.
One hundred twenty-six thousand eight hundred and eighty-seven dollars is housing-level money in Austin; in UT Austin’s new business-school building, it buys a single parking spot.
A long time ago, I came across a book called Chase, Chance, and Creativity: The Lucky Art of Novelty(《追逐、机遇和创造力:新奇的幸运艺术》). I no longer remember everything in it, but its central idea stayed somewhere in the back of my mind: luck and creativity are not entirely random. Chance may arrive unexpectedly, but we can still choose how often we encounter it and whether we are ready to recognize it.
很久以前,我偶然看到一本书,叫 Chase, Chance, and Creativity: The Lucky Art of Novelty(《追逐、机遇和创造力:新奇的幸运艺术》)。我已经不记得书里的全部内容了,但它的核心想法一直留在我脑海中的某个角落:运气和创造力并不完全是随机的。机遇也许会意外到来,但我们仍然可以选择自己遇见它的频率,以及当它出现时,我们是否已经准备好认出它。
A receipt in Singapore showed S$5.50, while a U.S. credit-card account displayed only US$4.27. Another purchase of about S$48 appeared as roughly US$38. A bank-card transit ride also failed to appear immediately as pending.
If you ask most people where trees in California get their water in a drought, they will say “the soil.” It turns out a huge fraction of it comes from cracks in the bedrock underneath the soil, and Daniella Rempe is the person who put numbers on it.
The US is full of small traps that nobody warns you about until after you’ve fallen into one. US Survival Guide is a handbook for Chinese students and newcomers on identifying risk early, knowing your rights, and building a financial defense before you need it. Read the Guide
Most crypto dashboards either drown you in numbers or hide the signal behind a paywall. Crypto Dashboard is my attempt at a clean, AI-augmented view of the market that runs entirely in your browser. Try Live Demo
Most enterprise security companies show up, ride one trend, and disappear in the next infrastructure cycle. Sean Xiang has been building Bloombase since January 2012, and the company has somehow been on the right side of every major infrastructure shift since, including the current AI accelerator era. That is not luck. That is a thesis.
A widely shared post describes a brainstorming meeting at a robotics startup in Boston. A slide said “No stupid questions.” A Chinese employee interpreted it as “Do not ask stupid questions,” while American colleagues explained it as “Ask freely; no question will be judged stupid.” A related post claims that “Say it again?” is neutral when someone is not heard, whereas “What did you say?” is hostile.
一张流传截图讲了这样一件事:一家波士顿机器人创业公司开头脑风暴会,幻灯片写着 “No stupid questions.” 一位中国员工把它理解为“不要问蠢问题”,美国同事却说它的意思是“什么都可以问,没有问题会被当成蠢问题”。另一组讨论又声称:没听清时说 “Say it again?” 很中性,而 “What did you say?” 很不友好。
The silence surrounding the Alamo chapel in San Antonio belies the brutal, thirteen-day siege that transformed this former Spanish mission into the ultimate symbol of Texan independence. Standing before its weathered facade today, one can almost hear the echoes of a conflict that remains one of the most legendary chapters in American history.
Most crypto dashboards either drown you in numbers or hide the signal behind a paywall. Crypto Dashboard is my attempt at a clean, AI-augmented view of the market that runs entirely in your browser. Try Live Demo
If I reopened the 2026 folder in 2030, I would check one thing first: did the work completed with AI change a real problem and leave evidence that others could verify and build upon?
At today’s Silicon Valley alumni “Ask a Question” AI meet-up, what I wanted to talk about wasn’t how cool Claude Code is, but how it actually re-slices real work.
Every indie developer who has ever burned through a free API tier knows the feeling: you build something cool, and then your OPENAI_API_KEY runs out at the worst possible moment. hao-tokens is a curated list of the legitimate ways to get free or low-cost LLM tokens so you can keep building.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
Most VCs and accelerators talk about supporting founders. Kehan Dong specifically supports the kind of founder who started building at 16, when nobody told them they were allowed to, and it turns out that population is dramatically underserved.
When you join a lab, you do not just get a research direction. You inherit a 30-year codebase that is currently running inside the U.S. National Water Model and was on the critical path forecasting Hurricane Harvey. That is what working with Zong-Liang Yang at the Jackson School of Geosciences actually looks like.
NASA’s Future Investigators in NASA Earth and Space Science and Technology (FINESST) is one of the most underused fellowships among US graduate students. Most PhD students have never heard of it, and the ones who have often miss the deadline because the proposal expectations aren’t obvious from the call alone. This repo is a curated guide of links, tips, and examples to help you write a competitive FINESST proposal.
Dr. Zong-Liang Yang’s Land Environment and Atmospheric Dynamics (LEAD) Group at UT-Austin employs satellite remote sensing, earth system modeling, and high-performance computing to advance understanding of Earth system sciences.
AlphaEarthHack is the project our team built for the UT Austin Geoscience Hackathon. The goal: see how far we could push AI on Earth system data inside a single weekend. Try Live Demo
Call it a (10^5) gap if you like, once you put semantic entropy and effective training samples on the board, the difference between internet-scale text and embodied robotics data stops sounding like rhetorical inflation and starts sounding almost conservative. You just have to separate raw physics bits from semantics a learner can actually use.
Decades of Earth-system modeling judgment live in PDFs, mailing lists, and senior researchers’ heads, and none of it is loadable by an AI coding agent. earth-space-ai.org is an attempt to fix that.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
The roar of cooling systems in the Texas Advanced Computing Center (TACC) isn’t just noise—it’s the power of supercomputers translating the overwhelming dimensionality of climate data into something students can finally see and understand.
Most land surface models treat a tree like a passive straw. Water comes in at the roots, water leaves at the leaves, end of story. Ashley Matheny’s research basically says no, a tree is an active hydraulic system with storage, capacitance, and a strategy, and if you do not model it that way you are going to be wrong about drought.
The signal truly worth heeding is not that AI companies are growing too slowly, but that they are growing fast while cash-flow pressure keeps mounting.
I joined Tsinghua University’s seminar series on the joint cultivation of top innovative talent as an invited student speaker. I shared a student’s view of cross-institution research training and the conditions that help young researchers pursue difficult questions.
Tsinghua News republished the People’s Daily Overseas Edition feature on Shenzhen X-Institute. The story describes the institute’s project-based education model and includes my experience of exploring research there as a USTC undergraduate.
The People’s Daily Overseas Edition featured Shenzhen X-Institute and its project-based approach to developing young innovators. I spoke about arriving at the institute as a USTC undergraduate, trying research across disciplines, and finding a community where students actively pursued their own questions.
Linchuan No. 1 Middle School published a congratulatory note when I was admitted to the University of Science and Technology of China. It records the transition from high school to the next stage of my education.
The article 教育变革的技术奇点时刻到来了吗? discusses whether technology is changing the conditions of education. My contribution draws on my experience as a USTC student participating in Shenzhen X-Institute’s project-based research environment.
China Science Daily’s WeChat edition tells how students who felt out of place in conventional university life found peers at Shenzhen X-Institute. My part follows the move from a difficult first year to leading a 3D-chip cooling project and completing the Senior Undergraduate Researcher Program.
China Science Daily profiled Shenzhen X-Institute’s approach to innovation education. The article follows my path from a difficult first year at university to a student-led 3D-chip cooling project, then situates that experience in an education model built around questions, mentors, peers, and room to experiment.
The sense of agency that took me more than twenty years to grow, these seventeen and eighteen year old students got far more easily, just by being at Stanford, being in America, or maybe going to high school in Shanghai first.
Rereading my old journals today, from nuclear fusion in physics to the games humans play, I keep finding the same thing. Whether it is a startup or a whole industry, what matters is a force that rises on its own and then keeps itself going.
School rankings are a single number standing in for a multi-dimensional decision. School Evaluator is a small web tool that lets you score a school across the dimensions that actually shape your life there. Try Live Demo
Earlier today I published a piece called “Four Ego Mistakes I Made as a 22-Year-Old Founder.” Then I ran it through Gemini 2.5 Pro as an independent reviewer. Gemini’s verdict was that the essay is itself an ego move. I think Gemini is mostly right.
Call it a (10^5) gap if you like, once you put semantic entropy and effective training samples on the board, the difference between internet-scale text and embodied robotics data stops sounding like rhetorical inflation and starts sounding almost conservative. You just have to separate raw physics bits from semantics a learner can actually use.
Most enterprise security companies show up, ride one trend, and disappear in the next infrastructure cycle. Sean Xiang has been building Bloombase since January 2012, and the company has somehow been on the right side of every major infrastructure shift since, including the current AI accelerator era. That is not luck. That is a thesis.
Most VCs and accelerators talk about supporting founders. Kehan Dong specifically supports the kind of founder who started building at 16, when nobody told them they were allowed to, and it turns out that population is dramatically underserved.
Research, stock trading, and startups all share a common pattern: success comes from combining a defensible core competency with the ability to ride trending waves. You don’t need exhaustive preparation anymore. You need methodology and the ability to produce content when it matters. When the right moment arrives, you strike.
The sense of agency that took me more than twenty years to grow, these seventeen and eighteen year old students got far more easily, just by being at Stanford, being in America, or maybe going to high school in Shanghai first.
As we walked out of the library, an elderly white woman with silver hair saw us and said “excuse me” three times. She spoke to us with real pride, took out her phone, and said she had seen the two of us taking photos with the frog statue out front. Every Christmas, she told us, that frog gets dressed up in a Christmas outfit, look, just like this! Then she asked, very sincerely, whether we would still be here at Christmas, and how we had even heard of Atherton, because the place is so unremarkable, so quiet, so low-key. We told her we would probably each be heading home by then. She added that her son had been learning Chinese since he was a little kid, and that he speaks it really well.
A bit of history from a casual chat: in the US, science students used to get bigger stipends than business, law or medicine students, because science students were poor.
Don’t expect your first video to go viral, and don’t expect your first sales trip to land ten million dollars, but you can ask what happens after the hundredth try.
Another day of heavy internet surfing, and the biggest lesson was this: there is no investment strategy that lets you lie down and get financially free.
Most crypto dashboards either drown you in numbers or hide the signal behind a paywall. Crypto Dashboard is my attempt at a clean, AI-augmented view of the market that runs entirely in your browser. Try Live Demo
I spent a whole evening with Gemini taking apart the Buy Borrow Die playbook that American billionaires run, expecting that with a little scaling down I could just copy the moves, and what I found instead was that almost every single move has an F-1 trapdoor underneath it, and the list of things I can actually do fits on one page.
The roar of cooling systems in the Texas Advanced Computing Center (TACC) isn’t just noise—it’s the power of supercomputers translating the overwhelming dimensionality of climate data into something students can finally see and understand.
I plugged a Western Digital external drive full of data into a MacBook Air, tried to copy a file onto it, and nothing happened. No error dialog, no progress bar, just a drive that would let me read everything and write nothing. My first instinct was that something was broken, or that I needed to fix permissions. Both were wrong, and chasing the wrong explanation almost led me to permanently downgrade the security of the whole laptop.
我把一块装满数据的西部数据(WD)移动硬盘插到 MacBook Air 上,想往里拷一个文件,结果什么都没发生。没有报错弹窗,没有进度条,就是一块能读出所有东西、却一个字节都写不进去的硬盘。我的第一反应是它坏了,或者是我得去修一下权限。这两个判断都是错的,而且顺着错误的解释找下去,差点让我把整台笔记本的安全性永久降级。
finance
Warren Buffett: The “Open Source” Leader Half a Century Before GitHub
巴菲特:比GitHub早了半个世纪的“开源”运动领袖
2 minute read
Published:
In an era driven by code, collaboration, and transparency, GitHub has become synonymous with the “open source” spirit. But if we turn our gaze to the world of finance, we find a pioneer of “open source” who predates the birth of GitHub by a full half-century. His name is Warren Buffett.
People love saying that ten years to a billion-dollar valuation is the normal pace for a unicorn, neither fast nor slow. But once you actually crunch the compound numbers, you realize what hides behind that word “normal” is a beast that doubles in value every single year.
The US is full of small traps that nobody warns you about until after you’ve fallen into one. US Survival Guide is a handbook for Chinese students and newcomers on identifying risk early, knowing your rights, and building a financial defense before you need it. Read the Guide
NASA’s Future Investigators in NASA Earth and Space Science and Technology (FINESST) is one of the most underused fellowships among US graduate students. Most PhD students have never heard of it, and the ones who have often miss the deadline because the proposal expectations aren’t obvious from the call alone. This repo is a curated guide of links, tips, and examples to help you write a competitive FINESST proposal.
Call it a (10^5) gap if you like, once you put semantic entropy and effective training samples on the board, the difference between internet-scale text and embodied robotics data stops sounding like rhetorical inflation and starts sounding almost conservative. You just have to separate raw physics bits from semantics a learner can actually use.
You can study fluid mechanics in five different countries before you turn 30, work on petroleum reservoirs and tectonophysics and planetary ice on the same week, and somehow end up at a Centennial Chair in Geophysics. Marc Hesse did exactly that, and the through-line is more interesting than any of the individual stops.
Rereading my old journals today, from nuclear fusion in physics to the games humans play, I keep finding the same thing. Whether it is a startup or a whole industry, what matters is a force that rises on its own and then keeps itself going.
In October 2023 I asked ChatGPT an over-engineered question: how do you fry rice so that every grain of rice ends up bonded to egg, with no bare rice grains and no isolated clumps of egg sitting off on their own? I saved that conversation as an HTML file, dropped it in my Downloads folder, and did not look at it again for almost three years. Last week I finally turned it into an actual open-source repo, and going back through the original conversation to build it was more interesting than I expected.
I’ve been playing with mixed-language builds (Fortran calling into C++ and C via iso_c_binding) and wanted a demo that was more interesting than “add two numbers across languages.” So I built fortran-zip-bomb: a small program that generates a genuine ZIP bomb — a small archive that expands into a much larger file on decompression.
The same way text foundation models ate NLP and image models ate computer vision, someone is going to build the foundation model that eats spatial reasoning. Gengchen Mai is one of the people taking that bet seriously, and his SEAI Lab at UT Austin is one of the places it is being built.
Most enterprise security companies show up, ride one trend, and disappear in the next infrastructure cycle. Sean Xiang has been building Bloombase since January 2012, and the company has somehow been on the right side of every major infrastructure shift since, including the current AI accelerator era. That is not luck. That is a thesis.
Earlier today I published a piece called “Four Ego Mistakes I Made as a 22-Year-Old Founder.” Then I ran it through Gemini 2.5 Pro as an independent reviewer. Gemini’s verdict was that the essay is itself an ego move. I think Gemini is mostly right.
When Large Language Models (LLMs) hallucinate, we often treat it as an engineering bug to be fixed. But what if hallucinations are not a flaw, but a mathematical inevitability? A recent interdisciplinary discussion revealed a profound connection between the Gibbs phenomenon in Fourier analysis and the fundamental limitations of neural networks.
Every indie developer who has ever burned through a free API tier knows the feeling: you build something cool, and then your OPENAI_API_KEY runs out at the worst possible moment. hao-tokens is a curated list of the legitimate ways to get free or low-cost LLM tokens so you can keep building.
Securing up to $150,000 in research funding over three years can define a graduate career, and NASA’s FINESST program is the primary vehicle for that transformation. This guide distills the complex application process into actionable strategies for Earth and Space Science researchers seeking to join the next generation of Future Investigators.
If I reopened the 2026 folder in 2030, I would check one thing first: did the work completed with AI change a real problem and leave evidence that others could verify and build upon?
Sometimes a piece of old science fiction stays in your head not because of the gadgets, but because it got the emotional structure of the future right.
Every knowledge worker is now competing with an LLM for some part of their job. AI Survival Guide is a handbook for figuring out which parts, what to do about it, and how to come out the other side better at your craft instead of replaced by it.
Virtual cell models powered by neuromorphic computing and gene language models represent one of the most capital-intensive and scientifically ambitious convergences in biotech AI. If you’re evaluating this space as a VC intern, you need to understand three core components: what these systems actually do, why the market is moving now, and where the investable opportunities lie.
I am deeply honored to join my colleagues in contributing to the newly published paper, “On the Ethics of Generative GeoAI: Explainability, Bias, Hallucination, Accountability, Privacy, and Trust,” specifically focusing on the section regarding GeoAI Trust (Section 8).
The same way text foundation models ate NLP and image models ate computer vision, someone is going to build the foundation model that eats spatial reasoning. Gengchen Mai is one of the people taking that bet seriously, and his SEAI Lab at UT Austin is one of the places it is being built.
AlphaEarthHack is the project our team built for the UT Austin Geoscience Hackathon. The goal: see how far we could push AI on Earth system data inside a single weekend. Try Live Demo
You can study fluid mechanics in five different countries before you turn 30, work on petroleum reservoirs and tectonophysics and planetary ice on the same week, and somehow end up at a Centennial Chair in Geophysics. Marc Hesse did exactly that, and the through-line is more interesting than any of the individual stops.
In my first post on this I described sending a patch through GitGitGadget and watching it land on the mailing list as v1. That post ended with the patch waiting for review. It has since merged. Now that I have seen the full lifecycle, from typo to master, here is what actually mattered.
In my first post on this I described sending a patch through GitGitGadget and watching it land on the mailing list as v1. That post ended with the patch waiting for review. It has since merged. Now that I have seen the full lifecycle, from typo to master, here is what actually mattered.
对技术人来说,在一个高速增长的开源仓库里做出高质量 PR,往往比再发一篇泛泛而谈的 AI 观点帖更像真正有效的 inbound marketing。
Warren Buffett: The “Open Source” Leader Half a Century Before GitHub
巴菲特:比GitHub早了半个世纪的“开源”运动领袖
2 minute read
Published:
In an era driven by code, collaboration, and transparency, GitHub has become synonymous with the “open source” spirit. But if we turn our gaze to the world of finance, we find a pioneer of “open source” who predates the birth of GitHub by a full half-century. His name is Warren Buffett.
When gold gets too expensive relative to silver, you sell your gold and buy silver. When silver catches up, you swap back. This sounds like folk wisdom, but it’s one of the most time-tested strategies in precious metals.
Every indie developer who has ever burned through a free API tier knows the feeling: you build something cool, and then your OPENAI_API_KEY runs out at the worst possible moment. hao-tokens is a curated list of the legitimate ways to get free or low-cost LLM tokens so you can keep building.
NASA’s Future Investigators in NASA Earth and Space Science and Technology (FINESST) is one of the most underused fellowships among US graduate students. Most PhD students have never heard of it, and the ones who have often miss the deadline because the proposal expectations aren’t obvious from the call alone. This repo is a curated guide of links, tips, and examples to help you write a competitive FINESST proposal.
Securing up to $150,000 in research funding over three years can define a graduate career, and NASA’s FINESST program is the primary vehicle for that transformation. This guide distills the complex application process into actionable strategies for Earth and Space Science researchers seeking to join the next generation of Future Investigators.
A PhD is hard. A PhD in 2026 — with the field moving faster than your committee can read — is a different kind of hard. AI PhD Survival Guide is a handbook for surviving and finishing an AI or ML PhD without burning out and without falling behind.
School rankings are a single number standing in for a multi-dimensional decision. School Evaluator is a small web tool that lets you score a school across the dimensions that actually shape your life there. Try Live Demo
Dr. Zong-Liang Yang’s Land Environment and Atmospheric Dynamics (LEAD) Group at UT-Austin employs satellite remote sensing, earth system modeling, and high-performance computing to advance understanding of Earth system sciences.
Hah, I can’t help but laugh. It just hit me: the first time I ever used Markdown was back when I was building a poetry society. And that’s also when I first learned about Git. Looking back now, if you put all the founding members of that poetry society together, you’d almost have two unicorns.
AlphaEarthHack is the project our team built for the UT Austin Geoscience Hackathon. The goal: see how far we could push AI on Earth system data inside a single weekend. Try Live Demo
I plugged a Western Digital external drive full of data into a MacBook Air, tried to copy a file onto it, and nothing happened. No error dialog, no progress bar, just a drive that would let me read everything and write nothing. My first instinct was that something was broken, or that I needed to fix permissions. Both were wrong, and chasing the wrong explanation almost led me to permanently downgrade the security of the whole laptop.
我把一块装满数据的西部数据(WD)移动硬盘插到 MacBook Air 上,想往里拷一个文件,结果什么都没发生。没有报错弹窗,没有进度条,就是一块能读出所有东西、却一个字节都写不进去的硬盘。我的第一反应是它坏了,或者是我得去修一下权限。这两个判断都是错的,而且顺着错误的解释找下去,差点让我把整台笔记本的安全性永久降级。
When an ordinary-looking “heart age” questionnaire lets you calculate that your heart is younger than your actual age, you may need to re-examine the lifestyle habits you’ve been ignoring.
Decades of Earth-system modeling judgment live in PDFs, mailing lists, and senior researchers’ heads, and none of it is loadable by an AI coding agent. earth-space-ai.org is an attempt to fix that.
A university’s favorite performance is to wait until a person no longer needs a medal, then ceremonially drape them in a gown embroidered with the word “Doctor.”
A PhD system built on a 19th-century apprenticeship model is failing by nearly every empirical measure — ~40–50% attrition, depression rates six times the general population, and tenure-track placement below 15% in many fields — while venture capital has spent four decades perfecting bilateral contracts that manage exactly the risks PhD programs ignore: information asymmetry, moral hazard, hold-up, and misaligned incentives. The literature across economics, education policy, signaling theory, and AI research converges on a striking conclusion: the structural tools to fix the PhD already exist in VC contract design, but academia has never imported them. This research compendium maps the evidentiary landscape across six domains to ground the argument.
Whether a civilization has logic is not decided by whether it produced a few brilliant arguers. Three tests decide it. Did anyone study inference itself and write books about it. Did the subject enter schools, with teachers who taught it and students who learned it. Did some institution, an examination above all, force generation after generation to master it. Greece passes all three tests. India passes all three. Ancient China fails every one.
The silence surrounding the Alamo chapel in San Antonio belies the brutal, thirteen-day siege that transformed this former Spanish mission into the ultimate symbol of Texan independence. Standing before its weathered facade today, one can almost hear the echoes of a conflict that remains one of the most legendary chapters in American history.
On May 17, 2025, I had about nine hours alone in Hong Kong between flights and trains, and I planned them around Victoria Harbour and the city’s richest commercial districts.
A university’s favorite performance is to wait until a person no longer needs a medal, then ceremonially drape them in a gown embroidered with the word “Doctor.”
I submitted our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation to Hugging Face Daily Papers on September 14, 2026, and readers voted it to the top of that day’s list. As of September 29 it has 171 upvotes, the most of the 26 papers posted that day.
2026 年 9 月 14 日,我把论文 Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation 提交到 Hugging Face Daily Papers,读者把它投上了当天榜首。截至 9 月 29 日,它获得 171 个赞,在当天 26 篇论文中排第一。
I ended up in the wrong NEXUS line at Vancouver International Airport. By the rules, the mistake was mine. By design, it was an almost predictable wrong turn.
If you ask most people where trees in California get their water in a drought, they will say “the soil.” It turns out a huge fraction of it comes from cracks in the bedrock underneath the soil, and Daniella Rempe is the person who put numbers on it.
Day thirty-one of Benchmark Radar. Every release card now carries a one-line summary instead of a bare version tag, filing an issue takes at most two required fields, and both READMEs got short enough to read. Scoreboard: 107 stars, 20 forks.
Day twenty-seven of Benchmark Radar. We made the Today list load a page at a time, cut a title in half, and taught 21 benchmarks to show their real names.
I spent a whole evening with Gemini taking apart the Buy Borrow Die playbook that American billionaires run, expecting that with a little scaling down I could just copy the moves, and what I found instead was that almost every single move has an F-1 trapdoor underneath it, and the list of things I can actually do fits on one page.
A laser lightsail accelerating to one percent of light speed turns about one percent of the beam into motion. The other ninety-nine percent leaves as light and does no work.
A long time ago, I came across a book called Chase, Chance, and Creativity: The Lucky Art of Novelty(《追逐、机遇和创造力:新奇的幸运艺术》). I no longer remember everything in it, but its central idea stayed somewhere in the back of my mind: luck and creativity are not entirely random. Chance may arrive unexpectedly, but we can still choose how often we encounter it and whether we are ready to recognize it.
很久以前,我偶然看到一本书,叫 Chase, Chance, and Creativity: The Lucky Art of Novelty(《追逐、机遇和创造力:新奇的幸运艺术》)。我已经不记得书里的全部内容了,但它的核心想法一直留在我脑海中的某个角落:运气和创造力并不完全是随机的。机遇也许会意外到来,但我们仍然可以选择自己遇见它的频率,以及当它出现时,我们是否已经准备好认出它。
When you go looking for a seat in the great theater of the AI era, built from PowerPoints, papers, and anxiety, it helps to look at which play each person on stage is performing.
Call it a (10^5) gap if you like, once you put semantic entropy and effective training samples on the board, the difference between internet-scale text and embodied robotics data stops sounding like rhetorical inflation and starts sounding almost conservative. You just have to separate raw physics bits from semantics a learner can actually use.
The promise of AI-automated science is intoxicating: imagine machines that can generate hypotheses, design experiments, and publish papers while we sleep.
Most enterprise security companies show up, ride one trend, and disappear in the next infrastructure cycle. Sean Xiang has been building Bloombase since January 2012, and the company has somehow been on the right side of every major infrastructure shift since, including the current AI accelerator era. That is not luck. That is a thesis.
Most VCs and accelerators talk about supporting founders. Kehan Dong specifically supports the kind of founder who started building at 16, when nobody told them they were allowed to, and it turns out that population is dramatically underserved.
Geepity turned our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation into a full interactive reading edition, walking through all nine chapters with live charts and a working BM25F demo.
A handcrafted website universe where every webpage, balloon, click, and line of code says “I love you” - designed exclusively for Momo. Visit Live Site
How photographing a black hole and training GPT-4 are fundamentally the same process: extracting coherent structure from impossibly sparse frequency-domain measurements.
I ended up in the wrong NEXUS line at Vancouver International Airport. By the rules, the mistake was mine. By design, it was an almost predictable wrong turn.
Beyond the wayfinding problem that led me into the wrong NEXUS line, my connection at Vancouver International Airport left me with several observations unrelated to signs. I noticed an older-looking mix of people, a departures area that offered almost nowhere to work, and a visible contrast between people in Vancouver and Texas. This post records those observations. The full account of the NEXUS incident is in How I “Reasonably” Ended Up in the Wrong NEXUS Line at YVR.
I spent a whole evening with Gemini taking apart the Buy Borrow Die playbook that American billionaires run, expecting that with a little scaling down I could just copy the moves, and what I found instead was that almost every single move has an F-1 trapdoor underneath it, and the list of things I can actually do fits on one page.
The US is full of small traps that nobody warns you about until after you’ve fallen into one. US Survival Guide is a handbook for Chinese students and newcomers on identifying risk early, knowing your rights, and building a financial defense before you need it. Read the Guide
From the vast datasets of Earth System Models to the specialized niches of high-performance computing, this space documents my journey as a PhD student at UT Austin pushing the boundaries of Geological and Earth Sciences. This website is more than just a portfolio—it’s a hub where data-driven climate science meets the practical challenges of modern research.
I spent a whole evening with Gemini taking apart the Buy Borrow Die playbook that American billionaires run, expecting that with a little scaling down I could just copy the moves, and what I found instead was that almost every single move has an F-1 trapdoor underneath it, and the list of things I can actually do fits on one page.
When gold gets too expensive relative to silver, you sell your gold and buy silver. When silver catches up, you swap back. This sounds like folk wisdom, but it’s one of the most time-tested strategies in precious metals.
Another day of heavy internet surfing, and the biggest lesson was this: there is no investment strategy that lets you lie down and get financially free.
“这b人生过的值不值” — roughly, “was this damn life worth it?” — is a phrase that does a lot of emotional work on the Chinese internet. ZuoGuoHuaDiao (做过划掉) is a small web tool that takes the phrase seriously and tries to answer it with numbers. Try Live Demo
Most people think of summer vacation as time off. I started wondering whether that framing undersells it. Summer Calculator is a small web tool that estimates the full value of your summer — money, learning, relationships, health — not just the days you didn’t work. Try Live Demo
A handcrafted website universe where every webpage, balloon, click, and line of code says “I love you” - designed exclusively for Momo. Visit Live Site
Lay out every hyped multiAgent product on a table in front of Steve Jobs and he would probably squint, frown, and ask one question, why on earth are you showing the user any of this.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
AlphaEarthHack is the project our team built for the UT Austin Geoscience Hackathon. The goal: see how far we could push AI on Earth system data inside a single weekend. Try Live Demo
The same way text foundation models ate NLP and image models ate computer vision, someone is going to build the foundation model that eats spatial reasoning. Gengchen Mai is one of the people taking that bet seriously, and his SEAI Lab at UT Austin is one of the places it is being built.
Lay out every hyped multiAgent product on a table in front of Steve Jobs and he would probably squint, frown, and ask one question, why on earth are you showing the user any of this.
Every knowledge worker is now competing with an LLM for some part of their job. AI Survival Guide is a handbook for figuring out which parts, what to do about it, and how to come out the other side better at your craft instead of replaced by it.
Whether a civilization has logic is not decided by whether it produced a few brilliant arguers. Three tests decide it. Did anyone study inference itself and write books about it. Did the subject enter schools, with teachers who taught it and students who learned it. Did some institution, an examination above all, force generation after generation to master it. Greece passes all three tests. India passes all three. Ancient China fails every one.
A widely shared post describes a brainstorming meeting at a robotics startup in Boston. A slide said “No stupid questions.” A Chinese employee interpreted it as “Do not ask stupid questions,” while American colleagues explained it as “Ask freely; no question will be judged stupid.” A related post claims that “Say it again?” is neutral when someone is not heard, whereas “What did you say?” is hostile.
一张流传截图讲了这样一件事:一家波士顿机器人创业公司开头脑风暴会,幻灯片写着 “No stupid questions.” 一位中国员工把它理解为“不要问蠢问题”,美国同事却说它的意思是“什么都可以问,没有问题会被当成蠢问题”。另一组讨论又声称:没听清时说 “Say it again?” 很中性,而 “What did you say?” 很不友好。
Starting a petition, founding a club, and joining a research effort someone else organized look like three different things. They all run into the same question: who decides, who puts in the time, and when something goes wrong, who bears the consequences?
The US is full of small traps that nobody warns you about until after you’ve fallen into one. US Survival Guide is a handbook for Chinese students and newcomers on identifying risk early, knowing your rights, and building a financial defense before you need it. Read the Guide
TQQQ is the 3x-leveraged Nasdaq-100 ETF. It is also one of the most asymmetric instruments retail investors touch — the upside is real, the drawdowns are brutal, and the daily-rebalance math means buy-and-hold doesn’t behave the way most people assume. TQQQ ML Trend is an experiment in using machine learning to predict the trend regime, not the price.
When an ordinary-looking “heart age” questionnaire lets you calculate that your heart is younger than your actual age, you may need to re-examine the lifestyle habits you’ve been ignoring.
As we walked out of the library, an elderly white woman with silver hair saw us and said “excuse me” three times. She spoke to us with real pride, took out her phone, and said she had seen the two of us taking photos with the frog statue out front. Every Christmas, she told us, that frog gets dressed up in a Christmas outfit, look, just like this! Then she asked, very sincerely, whether we would still be here at Christmas, and how we had even heard of Atherton, because the place is so unremarkable, so quiet, so low-key. We told her we would probably each be heading home by then. She added that her son had been learning Chinese since he was a little kid, and that he speaks it really well.
“这b人生过的值不值” — roughly, “was this damn life worth it?” — is a phrase that does a lot of emotional work on the Chinese internet. ZuoGuoHuaDiao (做过划掉) is a small web tool that takes the phrase seriously and tries to answer it with numbers. Try Live Demo
Most people think of summer vacation as time off. I started wondering whether that framing undersells it. Summer Calculator is a small web tool that estimates the full value of your summer — money, learning, relationships, health — not just the days you didn’t work. Try Live Demo
School rankings are a single number standing in for a multi-dimensional decision. School Evaluator is a small web tool that lets you score a school across the dimensions that actually shape your life there. Try Live Demo
arXivDaily, the Chinese arXiv digest with per-university pages, lists our paper on its Shanghai Jiao Tong University page, following the SJTU affiliation on the author list.
Sometimes a piece of old science fiction stays in your head not because of the gadgets, but because it got the emotional structure of the future right.
Moonlight, the AI research-reading companion by Corca, published a literature-review page for our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation.
Call it a (10^5) gap if you like, once you put semantic entropy and effective training samples on the board, the difference between internet-scale text and embodied robotics data stops sounding like rhetorical inflation and starts sounding almost conservative. You just have to separate raw physics bits from semantics a learner can actually use.
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
A PhD is hard. A PhD in 2026 — with the field moving faster than your committee can read — is a different kind of hard. AI PhD Survival Guide is a handbook for surviving and finishing an AI or ML PhD without burning out and without falling behind.
Every indie developer who has ever burned through a free API tier knows the feeling: you build something cool, and then your OPENAI_API_KEY runs out at the worst possible moment. hao-tokens is a curated list of the legitimate ways to get free or low-cost LLM tokens so you can keep building.
When Large Language Models (LLMs) hallucinate, we often treat it as an engineering bug to be fixed. But what if hallucinations are not a flaw, but a mathematical inevitability? A recent interdisciplinary discussion revealed a profound connection between the Gibbs phenomenon in Fourier analysis and the fundamental limitations of neural networks.
How photographing a black hole and training GPT-4 are fundamentally the same process: extracting coherent structure from impossibly sparse frequency-domain measurements.
The signal truly worth heeding is not that AI companies are growing too slowly, but that they are growing fast while cash-flow pressure keeps mounting.
Every knowledge worker is now competing with an LLM for some part of their job. AI Survival Guide is a handbook for figuring out which parts, what to do about it, and how to come out the other side better at your craft instead of replaced by it.
The talk that stayed with me at the Texas Symposium on Machine Learning, Responsible AI & Robotics 2026 was about extending language models, not just making them bigger.
Yuxuan and I have been discussing AI agent ideas for a while. Yesterday, we finally decided: we’re building Atomize, a task-breaking agent system evolved from Goblin Tools.
If you’re serious about understanding LLMs and AI engineering, Simon Willison’s Newsletter is one of the best resources out there. With over 38,000 subscribers, it provides detailed analysis on AI, LLMs, web engineering, open source, data science, and Python.
Most enterprise security companies show up, ride one trend, and disappear in the next infrastructure cycle. Sean Xiang has been building Bloombase since January 2012, and the company has somehow been on the right side of every major infrastructure shift since, including the current AI accelerator era. That is not luck. That is a thesis.
In a field where everyone gets pulled toward the next hot thing, Juan Santiago joined Stanford Mechanical Engineering in 1998 and has been there ever since, building one of the most consequential microfluidics labs on the planet. Long-term focus is its own competitive advantage.
Don’t expect your first video to go viral, and don’t expect your first sales trip to land ten million dollars, but you can ask what happens after the hundredth try.
A long time ago, I came across a book called Chase, Chance, and Creativity: The Lucky Art of Novelty(《追逐、机遇和创造力:新奇的幸运艺术》). I no longer remember everything in it, but its central idea stayed somewhere in the back of my mind: luck and creativity are not entirely random. Chance may arrive unexpectedly, but we can still choose how often we encounter it and whether we are ready to recognize it.
很久以前,我偶然看到一本书,叫 Chase, Chance, and Creativity: The Lucky Art of Novelty(《追逐、机遇和创造力:新奇的幸运艺术》)。我已经不记得书里的全部内容了,但它的核心想法一直留在我脑海中的某个角落:运气和创造力并不完全是随机的。机遇也许会意外到来,但我们仍然可以选择自己遇见它的频率,以及当它出现时,我们是否已经准备好认出它。
A PhD is hard. A PhD in 2026 — with the field moving faster than your committee can read — is a different kind of hard. AI PhD Survival Guide is a handbook for surviving and finishing an AI or ML PhD without burning out and without falling behind.
How photographing a black hole and training GPT-4 are fundamentally the same process: extracting coherent structure from impossibly sparse frequency-domain measurements.
The talk that stayed with me at the Texas Symposium on Machine Learning, Responsible AI & Robotics 2026 was about extending language models, not just making them bigger.
TQQQ is the 3x-leveraged Nasdaq-100 ETF. It is also one of the most asymmetric instruments retail investors touch — the upside is real, the drawdowns are brutal, and the daily-rebalance math means buy-and-hold doesn’t behave the way most people assume. TQQQ ML Trend is an experiment in using machine learning to predict the trend regime, not the price.
AlphaEarthHack is the project our team built for the UT Austin Geoscience Hackathon. The goal: see how far we could push AI on Earth system data inside a single weekend. Try Live Demo
I plugged a Western Digital external drive full of data into a MacBook Air, tried to copy a file onto it, and nothing happened. No error dialog, no progress bar, just a drive that would let me read everything and write nothing. My first instinct was that something was broken, or that I needed to fix permissions. Both were wrong, and chasing the wrong explanation almost led me to permanently downgrade the security of the whole laptop.
我把一块装满数据的西部数据(WD)移动硬盘插到 MacBook Air 上,想往里拷一个文件,结果什么都没发生。没有报错弹窗,没有进度条,就是一块能读出所有东西、却一个字节都写不进去的硬盘。我的第一反应是它坏了,或者是我得去修一下权限。这两个判断都是错的,而且顺着错误的解释找下去,差点让我把整台笔记本的安全性永久降级。
One account opened 58 pull requests in 10 days on benchmark-radar. Five were merged. I put the contribution policy into agent-pr-gate so other maintainers can copy it: before an AI agent starts PR work, it asks its human four questions and waits for the answers.
Most crypto dashboards either drown you in numbers or hide the signal behind a paywall. Crypto Dashboard is my attempt at a clean, AI-augmented view of the market that runs entirely in your browser. Try Live Demo
When Large Language Models (LLMs) hallucinate, we often treat it as an engineering bug to be fixed. But what if hallucinations are not a flaw, but a mathematical inevitability? A recent interdisciplinary discussion revealed a profound connection between the Gibbs phenomenon in Fourier analysis and the fundamental limitations of neural networks.
In a field where everyone gets pulled toward the next hot thing, Juan Santiago joined Stanford Mechanical Engineering in 1998 and has been there ever since, building one of the most consequential microfluidics labs on the planet. Long-term focus is its own competitive advantage.
Muck Rack now has a profile for me. Muck Rack is a media database that journalists and communications teams use to find people and track who has written or been written about.
Shenzhen X-Institute interviewed me for 寻找X-学子说:吴叩天:从零到一、创造无限. The conversation covers how I found research, learned to build projects, and thought about creating work from zero to one.
The USTC Student Club Association recorded the founding of the Xingyun Poetry Club, which I helped start. The club created a home for poetry readings, writing, and student-run cultural events; its activities and posts later reached more than 100,000 views across platforms.
USTC recognized my project with the 2023 Undergraduate Research Plan Outstanding Award. The project used WACCM-X and observations to study how the 2022 Tonga eruption disturbed the mesosphere and lower thermosphere.
USTC awarded my undergraduate thesis a 2024 Outstanding Graduation Thesis Award. The thesis studied the 2022 Tonga volcanic eruption’s disturbance of the mesosphere and lower thermosphere using WACCM-X simulations and observations.
I joined Tsinghua University’s seminar series on the joint cultivation of top innovative talent as an invited student speaker. I shared a student’s view of cross-institution research training and the conditions that help young researchers pursue difficult questions.
Tsinghua News republished the People’s Daily Overseas Edition feature on Shenzhen X-Institute. The story describes the institute’s project-based education model and includes my experience of exploring research there as a USTC undergraduate.
机器之心 (Synced) covered MatrAIx, the population-scale simulated-user evaluation framework I coauthored. The article introduces Persona 8B and the environments where persona agents can answer surveys, talk with chatbots, browse websites, and use apps.
机器之心 (Synced) covered ASI-Bench, a benchmark I coauthored for evaluating AI agents on scientific research. The benchmark contains 60 research-grade tasks across 11 scientific domains.
I contributed to the startup documentary Starting Point One. The film records early-stage builders and the choices behind starting something from zero.
瀚海奇点 covered USTC’s 2021 Science Fiction Night. I took part in the event, which brought students together around science fiction, ideas, and creative work.
CatalyzeX now has an author page for me. CatalyzeX pairs machine learning papers with the code that goes with them, so a reader who finds a paper can jump straight to a working version instead of rebuilding it from the PDF.
AIModels.fyi now has an author page for me. The site turns new AI research papers into short summaries in plain English, so people who build with AI can keep up without reading every PDF.
500AI keeps an index of AI researchers, and it now has a page for me. It lists me as a Ph.D. student in Geological Sciences and a graduate research assistant at the University of Texas at Austin, tags my work under information retrieval and evaluation, and links out to this site, GitHub, LinkedIn, X, Google Scholar, and my UT Jackson School page.
ResearchSkills.ai is a directory for reusable AI skills built for research workflows. It helps researchers find and share tools for literature work, analysis, writing, and other parts of the research process.
My publications index gathers my papers across earth science, AI for science, and AI evaluation. Each entry links to the work and its available project resources.
Planetary Science featured our research on the spatial and temporal distribution of meteor speed and flux observed by a midlatitude meteor radar. The work uses radar observations to study how meteors vary across time and viewing geometry.
The People’s Daily Overseas Edition featured Shenzhen X-Institute and its project-based approach to developing young innovators. I spoke about arriving at the institute as a USTC undergraduate, trying research across disciplines, and finding a community where students actively pursued their own questions.
WIRED Czech introduced MatrAIx and Persona 8B to its readers. The short News Beat item highlights 8.3 billion digital profiles described across 1,290 categorical dimensions.
NZZ am Sonntag featured MatrAIx in a story about eight billion digital counterparts. The coverage introduces the scale of Persona 8B and the idea of using diverse simulated users to evaluate products and AI systems.
Numerama published a detailed explanation of MatrAIx. It distinguishes the 8.3 billion persona records from simultaneously running agents and discusses model dependence, representativeness, privacy, and the role of human panels.
Hugging Face Daily Papers featured MatrAIx as the number-two paper of the day. Its paper page collects the abstract, author list, discussion, and links to project resources in one place.
Forbes Türkiye examined how MatrAIx could help test health applications before they reach patients. The article focuses on variation in age, language, health literacy, and accessibility, while keeping clinical responsibility with people.
I appeared in Episode 1 of Mango TV’s Gold Rush 2026 (《夺金2026》) as a young founder working in Austin. The segment offers a brief television snapshot of the projects and questions I was pursuing at the time.
Linchuan No. 1 Middle School published a congratulatory note when I was admitted to the University of Science and Technology of China. It records the transition from high school to the next stage of my education.
Forbes covered MatrAIx, a study I coauthored, as a new research instrument for psychology. The article explains how population-scale AI personas can make experiments faster and easier to repeat while stressing that simulated users are not substitutes for people.
The article 教育变革的技术奇点时刻到来了吗? discusses whether technology is changing the conditions of education. My contribution draws on my experience as a USTC student participating in Shenzhen X-Institute’s project-based research environment.
China Science Daily’s WeChat edition tells how students who felt out of place in conventional university life found peers at Shenzhen X-Institute. My part follows the move from a difficult first year to leading a 3D-chip cooling project and completing the Senior Undergraduate Researcher Program.
China Science Daily profiled Shenzhen X-Institute’s approach to innovation education. The article follows my path from a difficult first year at university to a student-led 3D-chip cooling project, then situates that experience in an education model built around questions, mentors, peers, and room to experiment.
I submitted our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation to Hugging Face Daily Papers on September 14, 2026, and readers voted it to the top of that day’s list. As of September 29 it has 171 upvotes, the most of the 26 papers posted that day.
2026 年 9 月 14 日,我把论文 Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation 提交到 Hugging Face Daily Papers,读者把它投上了当天榜首。截至 9 月 29 日,它获得 171 个赞,在当天 26 篇论文中排第一。
The Isfahan AI Desk (میز هوش مصنوعی استان اصفهان), the province’s AI governance and ecosystem watch, listed our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation (arXiv:2609.11115) in its news radar with a relevance score of 91/100.
伊斯法罕省 AI 治理与生态观察(میز هوش مصنوعی استان اصفهان)把我们的论文 Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation(arXiv:2609.11115)列入新闻雷达,相关度评分 91/100。
Strongly Typed AI News, the AI news site Alexy Khrabrov runs at collected.ga, made our paper the lead story of its September 12, 2026 “Typesafe AI Daily” issue. Its crawler checked 49 sources that day and found 12 strong signals across AI infrastructure, funding, research, and developer tools, and it named Benchmark Radar the strongest of them.
Papers with Code listed our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation (arXiv:2609.11115), with its TL;DR, abstract, code repository, and project page.
Moonlight, the AI research-reading companion by Corca, published a literature-review page for our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation.
Geepity turned our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation into a full interactive reading edition, walking through all nine chapters with live charts and a working BM25F demo.
DailyAIWire covered the Benchmark Radar launch as a centralized AI evaluation database, with an AI-assisted intelligence report, an explain-like-I’m-five summary, and a visual flow of the system.
arXivDaily, the Chinese arXiv digest with per-university pages, lists our paper on its Shanghai Jiao Tong University page, following the SJTU affiliation on the author list.
alphaXiv hosts a discussion page for our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation, with the abstract, author list, BibTeX citation, and open discussion.
Port Aransas South Jetty published an Institute Insights feature on May 28, 2026 about how our University of Texas team is using satellite remote sensing and AI to monitor Texas coastal water quality.
UT01 is a free, student-built collection of resources for The University of Texas at Austin. It brings practical campus information and community projects into one public site.
When you join a lab, you do not just get a research direction. You inherit a 30-year codebase that is currently running inside the U.S. National Water Model and was on the critical path forecasting Hurricane Harvey. That is what working with Zong-Liang Yang at the Jackson School of Geosciences actually looks like.
Most VCs and accelerators talk about supporting founders. Kehan Dong specifically supports the kind of founder who started building at 16, when nobody told them they were allowed to, and it turns out that population is dramatically underserved.
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
Most of biology is averages. You measure a million cells, you get a mean. Eric Greene’s lab figured out how to actually watch one DNA molecule at a time, repair itself, in real time, and that changes what kind of questions biology can ask.
Goal: Use a 4x3 grid to place every relevant person “by position, with a matching strategy,” then review it regularly to maximize resource use and manage risk.
To be totally honest with you, you don’t need to understand the underlying architecture of large language models to get your name on a top-tier AI paper right now, you just need to be a true expert in your own field.
At the Metropolitan Museum of Art in New York, I walked into a real ancient Egyptian tomb, not a replica or a model, but a tomb that stood in the Egyptian desert more than four thousand years ago and was moved whole to Manhattan.
In a field where everyone gets pulled toward the next hot thing, Juan Santiago joined Stanford Mechanical Engineering in 1998 and has been there ever since, building one of the most consequential microfluidics labs on the planet. Long-term focus is its own competitive advantage.
In October 2023 I asked ChatGPT an over-engineered question: how do you fry rice so that every grain of rice ends up bonded to egg, with no bare rice grains and no isolated clumps of egg sitting off on their own? I saved that conversation as an HTML file, dropped it in my Downloads folder, and did not look at it again for almost three years. Last week I finally turned it into an actual open-source repo, and going back through the original conversation to build it was more interesting than I expected.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
Lay out every hyped multiAgent product on a table in front of Steve Jobs and he would probably squint, frown, and ask one question, why on earth are you showing the user any of this.
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
NASA’s Future Investigators in NASA Earth and Space Science and Technology (FINESST) is one of the most underused fellowships among US graduate students. Most PhD students have never heard of it, and the ones who have often miss the deadline because the proposal expectations aren’t obvious from the call alone. This repo is a curated guide of links, tips, and examples to help you write a competitive FINESST proposal.
Securing up to $150,000 in research funding over three years can define a graduate career, and NASA’s FINESST program is the primary vehicle for that transformation. This guide distills the complex application process into actionable strategies for Earth and Space Science researchers seeking to join the next generation of Future Investigators.
Virtual cell models powered by neuromorphic computing and gene language models represent one of the most capital-intensive and scientifically ambitious convergences in biotech AI. If you’re evaluating this space as a VC intern, you need to understand three core components: what these systems actually do, why the market is moving now, and where the investable opportunities lie.
At the Metropolitan Museum of Art in New York, I walked into a real ancient Egyptian tomb, not a replica or a model, but a tomb that stood in the Egyptian desert more than four thousand years ago and was moved whole to Manhattan.
Strongly Typed AI News, the AI news site Alexy Khrabrov runs at collected.ga, made our paper the lead story of its September 12, 2026 “Typesafe AI Daily” issue. Its crawler checked 49 sources that day and found 12 strong signals across AI infrastructure, funding, research, and developer tools, and it named Benchmark Radar the strongest of them.
If you’re serious about understanding LLMs and AI engineering, Simon Willison’s Newsletter is one of the best resources out there. With over 38,000 subscribers, it provides detailed analysis on AI, LLMs, web engineering, open source, data science, and Python.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
When you go looking for a seat in the great theater of the AI era, built from PowerPoints, papers, and anxiety, it helps to look at which play each person on stage is performing.
Decades of Earth-system modeling judgment live in PDFs, mailing lists, and senior researchers’ heads, and none of it is loadable by an AI coding agent. earth-space-ai.org is an attempt to fix that.
One account opened 58 pull requests in 10 days on benchmark-radar. Five were merged. I put the contribution policy into agent-pr-gate so other maintainers can copy it: before an AI agent starts PR work, it asks its human four questions and waits for the answers.
In October 2023 I asked ChatGPT an over-engineered question: how do you fry rice so that every grain of rice ends up bonded to egg, with no bare rice grains and no isolated clumps of egg sitting off on their own? I saved that conversation as an HTML file, dropped it in my Downloads folder, and did not look at it again for almost three years. Last week I finally turned it into an actual open-source repo, and going back through the original conversation to build it was more interesting than I expected.
In my first post on this I described sending a patch through GitGitGadget and watching it land on the mailing list as v1. That post ended with the patch waiting for review. It has since merged. Now that I have seen the full lifecycle, from typo to master, here is what actually mattered.
Yuxuan and I have been discussing AI agent ideas for a while. Yesterday, we finally decided: we’re building Atomize, a task-breaking agent system evolved from Goblin Tools.
If you’re serious about understanding LLMs and AI engineering, Simon Willison’s Newsletter is one of the best resources out there. With over 38,000 subscribers, it provides detailed analysis on AI, LLMs, web engineering, open source, data science, and Python.
Every indie developer who has ever burned through a free API tier knows the feeling: you build something cool, and then your OPENAI_API_KEY runs out at the worst possible moment. hao-tokens is a curated list of the legitimate ways to get free or low-cost LLM tokens so you can keep building.
Every generation has its own way of managing work: paper notebooks, SaaS task managers, and now programmable agentic workflows powered by tools like OpenClaw heartbeat.
Warren Buffett: The “Open Source” Leader Half a Century Before GitHub
巴菲特:比GitHub早了半个世纪的“开源”运动领袖
2 minute read
Published:
In an era driven by code, collaboration, and transparency, GitHub has become synonymous with the “open source” spirit. But if we turn our gaze to the world of finance, we find a pioneer of “open source” who predates the birth of GitHub by a full half-century. His name is Warren Buffett.
When gold gets too expensive relative to silver, you sell your gold and buy silver. When silver catches up, you swap back. This sounds like folk wisdom, but it’s one of the most time-tested strategies in precious metals.
I submitted our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation to Hugging Face Daily Papers on September 14, 2026, and readers voted it to the top of that day’s list. As of September 29 it has 171 upvotes, the most of the 26 papers posted that day.
2026 年 9 月 14 日,我把论文 Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation 提交到 Hugging Face Daily Papers,读者把它投上了当天榜首。截至 9 月 29 日,它获得 171 个赞,在当天 26 篇论文中排第一。
The Isfahan AI Desk (میز هوش مصنوعی استان اصفهان), the province’s AI governance and ecosystem watch, listed our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation (arXiv:2609.11115) in its news radar with a relevance score of 91/100.
伊斯法罕省 AI 治理与生态观察(میز هوش مصنوعی استان اصفهان)把我们的论文 Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation(arXiv:2609.11115)列入新闻雷达,相关度评分 91/100。
Strongly Typed AI News, the AI news site Alexy Khrabrov runs at collected.ga, made our paper the lead story of its September 12, 2026 “Typesafe AI Daily” issue. Its crawler checked 49 sources that day and found 12 strong signals across AI infrastructure, funding, research, and developer tools, and it named Benchmark Radar the strongest of them.
Papers with Code listed our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation (arXiv:2609.11115), with its TL;DR, abstract, code repository, and project page.
Moonlight, the AI research-reading companion by Corca, published a literature-review page for our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation.
Geepity turned our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation into a full interactive reading edition, walking through all nine chapters with live charts and a working BM25F demo.
DailyAIWire covered the Benchmark Radar launch as a centralized AI evaluation database, with an AI-assisted intelligence report, an explain-like-I’m-five summary, and a visual flow of the system.
arXivDaily, the Chinese arXiv digest with per-university pages, lists our paper on its Shanghai Jiao Tong University page, following the SJTU affiliation on the author list.
alphaXiv hosts a discussion page for our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation, with the abstract, author list, BibTeX citation, and open discussion.
Papers with Code listed our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation (arXiv:2609.11115), with its TL;DR, abstract, code repository, and project page.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
One hundred twenty-six thousand eight hundred and eighty-seven dollars is housing-level money in Austin; in UT Austin’s new business-school building, it buys a single parking spot.
In a field where everyone gets pulled toward the next hot thing, Juan Santiago joined Stanford Mechanical Engineering in 1998 and has been there ever since, building one of the most consequential microfluidics labs on the planet. Long-term focus is its own competitive advantage.
A receipt in Singapore showed S$5.50, while a U.S. credit-card account displayed only US$4.27. Another purchase of about S$48 appeared as roughly US$38. A bank-card transit ride also failed to appear immediately as pending.
A handcrafted website universe where every webpage, balloon, click, and line of code says “I love you” - designed exclusively for Momo. Visit Live Site
I spent a whole evening with Gemini taking apart the Buy Borrow Die playbook that American billionaires run, expecting that with a little scaling down I could just copy the moves, and what I found instead was that almost every single move has an F-1 trapdoor underneath it, and the list of things I can actually do fits on one page.
A PhD is hard. A PhD in 2026 — with the field moving faster than your committee can read — is a different kind of hard. AI PhD Survival Guide is a handbook for surviving and finishing an AI or ML PhD without burning out and without falling behind.
A PhD system built on a 19th-century apprenticeship model is failing by nearly every empirical measure — ~40–50% attrition, depression rates six times the general population, and tenure-track placement below 15% in many fields — while venture capital has spent four decades perfecting bilateral contracts that manage exactly the risks PhD programs ignore: information asymmetry, moral hazard, hold-up, and misaligned incentives. The literature across economics, education policy, signaling theory, and AI research converges on a striking conclusion: the structural tools to fix the PhD already exist in VC contract design, but academia has never imported them. This research compendium maps the evidentiary landscape across six domains to ground the argument.
A bit of history from a casual chat: in the US, science students used to get bigger stipends than business, law or medicine students, because science students were poor.
NASA’s Future Investigators in NASA Earth and Space Science and Technology (FINESST) is one of the most underused fellowships among US graduate students. Most PhD students have never heard of it, and the ones who have often miss the deadline because the proposal expectations aren’t obvious from the call alone. This repo is a curated guide of links, tips, and examples to help you write a competitive FINESST proposal.
Whether a civilization has logic is not decided by whether it produced a few brilliant arguers. Three tests decide it. Did anyone study inference itself and write books about it. Did the subject enter schools, with teachers who taught it and students who learned it. Did some institution, an examination above all, force generation after generation to master it. Greece passes all three tests. India passes all three. Ancient China fails every one.
The promise of AI-automated science is intoxicating: imagine machines that can generate hypotheses, design experiments, and publish papers while we sleep.
In October 2023 I asked ChatGPT an over-engineered question: how do you fry rice so that every grain of rice ends up bonded to egg, with no bare rice grains and no isolated clumps of egg sitting off on their own? I saved that conversation as an HTML file, dropped it in my Downloads folder, and did not look at it again for almost three years. Last week I finally turned it into an actual open-source repo, and going back through the original conversation to build it was more interesting than I expected.
Top physics researchers aren’t blind to what AI is doing in the application layer. They’re locked by their own evaluation system and can’t afford to look.
How photographing a black hole and training GPT-4 are fundamentally the same process: extracting coherent structure from impossibly sparse frequency-domain measurements.
You can study fluid mechanics in five different countries before you turn 30, work on petroleum reservoirs and tectonophysics and planetary ice on the same week, and somehow end up at a Centennial Chair in Geophysics. Marc Hesse did exactly that, and the through-line is more interesting than any of the individual stops.
NASA’s Future Investigators in NASA Earth and Space Science and Technology (FINESST) is one of the most underused fellowships among US graduate students. Most PhD students have never heard of it, and the ones who have often miss the deadline because the proposal expectations aren’t obvious from the call alone. This repo is a curated guide of links, tips, and examples to help you write a competitive FINESST proposal.
On May 17, 2025, I had about nine hours alone in Hong Kong between flights and trains, and I planned them around Victoria Harbour and the city’s richest commercial districts.
Most land surface models treat a tree like a passive straw. Water comes in at the roots, water leaves at the leaves, end of story. Ashley Matheny’s research basically says no, a tree is an active hydraulic system with storage, capacitance, and a strategy, and if you do not model it that way you are going to be wrong about drought.
If you ask most people where trees in California get their water in a drought, they will say “the soil.” It turns out a huge fraction of it comes from cracks in the bedrock underneath the soil, and Daniella Rempe is the person who put numbers on it.
Most academic climate scientists will tell you they care about policy and then publish a paper that no policymaker is ever going to read. Geeta Persad spent four years working at the Union of Concerned Scientists translating climate models for water managers, and she came back to academia knowing exactly what the gap looks like.
Top physics researchers aren’t blind to what AI is doing in the application layer. They’re locked by their own evaluation system and can’t afford to look.
When gold gets too expensive relative to silver, you sell your gold and buy silver. When silver catches up, you swap back. This sounds like folk wisdom, but it’s one of the most time-tested strategies in precious metals.
A PhD system built on a 19th-century apprenticeship model is failing by nearly every empirical measure — ~40–50% attrition, depression rates six times the general population, and tenure-track placement below 15% in many fields — while venture capital has spent four decades perfecting bilateral contracts that manage exactly the risks PhD programs ignore: information asymmetry, moral hazard, hold-up, and misaligned incentives. The literature across economics, education policy, signaling theory, and AI research converges on a striking conclusion: the structural tools to fix the PhD already exist in VC contract design, but academia has never imported them. This research compendium maps the evidentiary landscape across six domains to ground the argument.
Parameterizing a large Fortran climate model by hand is slow, error-prone, and hard to validate. Noah-Agent asks whether a team of specialized AI agents can do it instead.
The Isfahan AI Desk (میز هوش مصنوعی استان اصفهان), the province’s AI governance and ecosystem watch, listed our paper Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation (arXiv:2609.11115) in its news radar with a relevance score of 91/100.
伊斯法罕省 AI 治理与生态观察(میز هوش مصنوعی استان اصفهان)把我们的论文 Benchmark Radar: A Living Database and Search Engine for AI Benchmarks and Evaluation(arXiv:2609.11115)列入新闻雷达,相关度评分 91/100。
DailyAIWire covered the Benchmark Radar launch as a centralized AI evaluation database, with an AI-assisted intelligence report, an explain-like-I’m-five summary, and a visual flow of the system.
Exchanging money for time is a privilege I rarely indulge in, but a surprise membership benefit that cleared airport security in ten minutes changed my perspective on friction and market regulation. While a Clear Plus membership normally costs over a hundred dollars annually, obtaining it for free through an Uber membership allowed me to experience a level of efficiency that money can’t always buy—at least not without a well-regulated system behind it.
Lay out every hyped multiAgent product on a table in front of Steve Jobs and he would probably squint, frown, and ask one question, why on earth are you showing the user any of this.
Yuxuan and I have been discussing AI agent ideas for a while. Yesterday, we finally decided: we’re building Atomize, a task-breaking agent system evolved from Goblin Tools.
Goal: Use a 4x3 grid to place every relevant person “by position, with a matching strategy,” then review it regularly to maximize resource use and manage risk.
Every knowledge worker is now competing with an LLM for some part of their job. AI Survival Guide is a handbook for figuring out which parts, what to do about it, and how to come out the other side better at your craft instead of replaced by it.
Every generation has its own way of managing work: paper notebooks, SaaS task managers, and now programmable agentic workflows powered by tools like OpenClaw heartbeat.
Yuxuan and I have been discussing AI agent ideas for a while. Yesterday, we finally decided: we’re building Atomize, a task-breaking agent system evolved from Goblin Tools.
Don’t expect your first video to go viral, and don’t expect your first sales trip to land ten million dollars, but you can ask what happens after the hundredth try.
“这b人生过的值不值” — roughly, “was this damn life worth it?” — is a phrase that does a lot of emotional work on the Chinese internet. ZuoGuoHuaDiao (做过划掉) is a small web tool that takes the phrase seriously and tries to answer it with numbers. Try Live Demo
Most people think of summer vacation as time off. I started wondering whether that framing undersells it. Summer Calculator is a small web tool that estimates the full value of your summer — money, learning, relationships, health — not just the days you didn’t work. Try Live Demo
Muck Rack now has a profile for me. Muck Rack is a media database that journalists and communications teams use to find people and track who has written or been written about.
Shenzhen X-Institute interviewed me for 寻找X-学子说:吴叩天:从零到一、创造无限. The conversation covers how I found research, learned to build projects, and thought about creating work from zero to one.
CatalyzeX now has an author page for me. CatalyzeX pairs machine learning papers with the code that goes with them, so a reader who finds a paper can jump straight to a working version instead of rebuilding it from the PDF.
AIModels.fyi now has an author page for me. The site turns new AI research papers into short summaries in plain English, so people who build with AI can keep up without reading every PDF.
500AI keeps an index of AI researchers, and it now has a page for me. It lists me as a Ph.D. student in Geological Sciences and a graduate research assistant at the University of Texas at Austin, tags my work under information retrieval and evaluation, and links out to this site, GitHub, LinkedIn, X, Google Scholar, and my UT Jackson School page.
My publications index gathers my papers across earth science, AI for science, and AI evaluation. Each entry links to the work and its available project resources.
ResearchSkills.ai is a directory for reusable AI skills built for research workflows. It helps researchers find and share tools for literature work, analysis, writing, and other parts of the research process.
UT01 is a free, student-built collection of resources for The University of Texas at Austin. It brings practical campus information and community projects into one public site.
NASA’s Future Investigators in NASA Earth and Space Science and Technology (FINESST) is one of the most underused fellowships among US graduate students. Most PhD students have never heard of it, and the ones who have often miss the deadline because the proposal expectations aren’t obvious from the call alone. This repo is a curated guide of links, tips, and examples to help you write a competitive FINESST proposal.
One hundred twenty-six thousand eight hundred and eighty-seven dollars is housing-level money in Austin; in UT Austin’s new business-school building, it buys a single parking spot.
I am deeply honored to join my colleagues in contributing to the newly published paper, “On the Ethics of Generative GeoAI: Explainability, Bias, Hallucination, Accountability, Privacy, and Trust,” specifically focusing on the section regarding GeoAI Trust (Section 8).
If you’re serious about understanding LLMs and AI engineering, Simon Willison’s Newsletter is one of the best resources out there. With over 38,000 subscribers, it provides detailed analysis on AI, LLMs, web engineering, open source, data science, and Python.
TQQQ is the 3x-leveraged Nasdaq-100 ETF. It is also one of the most asymmetric instruments retail investors touch — the upside is real, the drawdowns are brutal, and the daily-rebalance math means buy-and-hold doesn’t behave the way most people assume. TQQQ ML Trend is an experiment in using machine learning to predict the trend regime, not the price.
Another day of heavy internet surfing, and the biggest lesson was this: there is no investment strategy that lets you lie down and get financially free.
TQQQ is the 3x-leveraged Nasdaq-100 ETF. It is also one of the most asymmetric instruments retail investors touch — the upside is real, the drawdowns are brutal, and the daily-rebalance math means buy-and-hold doesn’t behave the way most people assume. TQQQ ML Trend is an experiment in using machine learning to predict the trend regime, not the price.
A hand-controlled 3D visualization of your AI conversation history - fly through ChatGPT conversations and explore artificial intelligence concepts. Try Live Demo
Most crypto dashboards either drown you in numbers or hide the signal behind a paywall. Crypto Dashboard is my attempt at a clean, AI-augmented view of the market that runs entirely in your browser. Try Live Demo
Starting a petition, founding a club, and joining a research effort someone else organized look like three different things. They all run into the same question: who decides, who puts in the time, and when something goes wrong, who bears the consequences?
A laser lightsail accelerating to one percent of light speed turns about one percent of the beam into motion. The other ninety-nine percent leaves as light and does no work.
If I reopened the 2026 folder in 2030, I would check one thing first: did the work completed with AI change a real problem and leave evidence that others could verify and build upon?
The thing that almost stranded me on this international trip was not a typhoon, but several unrelated systems deciding at the same time that they did not trust me.
In my first post on this I described sending a patch through GitGitGadget and watching it land on the mailing list as v1. That post ended with the patch waiting for review. It has since merged. Now that I have seen the full lifecycle, from typo to master, here is what actually mattered.
Recently I’ve sometimes felt confused by how far AI has come, a bit lost and anxious, unsure what I should do, and then, because of my identity and my path, wondering what fallbacks or better options exist.
While you’re still grinding your heart out on “if you just work hard enough, you can move up,” you may not realize the system was never designed to cultivate you in the first place, it was designed to screen you.
Hah, I can’t help but laugh. It just hit me: the first time I ever used Markdown was back when I was building a poetry society. And that’s also when I first learned about Git. Looking back now, if you put all the founding members of that poetry society together, you’d almost have two unicorns.
Earlier today I published a piece called “Four Ego Mistakes I Made as a 22-Year-Old Founder.” Then I ran it through Gemini 2.5 Pro as an independent reviewer. Gemini’s verdict was that the essay is itself an ego move. I think Gemini is mostly right.
“这b人生过的值不值” — roughly, “was this damn life worth it?” — is a phrase that does a lot of emotional work on the Chinese internet. ZuoGuoHuaDiao (做过划掉) is a small web tool that takes the phrase seriously and tries to answer it with numbers. Try Live Demo
Goal: Use a 4x3 grid to place every relevant person “by position, with a matching strategy,” then review it regularly to maximize resource use and manage risk.
Port Aransas South Jetty published an Institute Insights feature on May 28, 2026 about how our University of Texas team is using satellite remote sensing and AI to monitor Texas coastal water quality.
机器之心 (Synced) covered MatrAIx, the population-scale simulated-user evaluation framework I coauthored. The article introduces Persona 8B and the environments where persona agents can answer surveys, talk with chatbots, browse websites, and use apps.
机器之心 (Synced) covered ASI-Bench, a benchmark I coauthored for evaluating AI agents on scientific research. The benchmark contains 60 research-grade tasks across 11 scientific domains.
Planetary Science featured our research on the spatial and temporal distribution of meteor speed and flux observed by a midlatitude meteor radar. The work uses radar observations to study how meteors vary across time and viewing geometry.
WIRED Czech introduced MatrAIx and Persona 8B to its readers. The short News Beat item highlights 8.3 billion digital profiles described across 1,290 categorical dimensions.
NZZ am Sonntag featured MatrAIx in a story about eight billion digital counterparts. The coverage introduces the scale of Persona 8B and the idea of using diverse simulated users to evaluate products and AI systems.
Numerama published a detailed explanation of MatrAIx. It distinguishes the 8.3 billion persona records from simultaneously running agents and discusses model dependence, representativeness, privacy, and the role of human panels.
Hugging Face Daily Papers featured MatrAIx as the number-two paper of the day. Its paper page collects the abstract, author list, discussion, and links to project resources in one place.
Forbes Türkiye examined how MatrAIx could help test health applications before they reach patients. The article focuses on variation in age, language, health literacy, and accessibility, while keeping clinical responsibility with people.
Forbes covered MatrAIx, a study I coauthored, as a new research instrument for psychology. The article explains how population-scale AI personas can make experiments faster and easier to repeat while stressing that simulated users are not substitutes for people.
Starting a petition, founding a club, and joining a research effort someone else organized look like three different things. They all run into the same question: who decides, who puts in the time, and when something goes wrong, who bears the consequences?
I am deeply honored to join my colleagues in contributing to the newly published paper, “On the Ethics of Generative GeoAI: Explainability, Bias, Hallucination, Accountability, Privacy, and Trust,” specifically focusing on the section regarding GeoAI Trust (Section 8).
Top physics researchers aren’t blind to what AI is doing in the application layer. They’re locked by their own evaluation system and can’t afford to look.
A PhD is hard. A PhD in 2026 — with the field moving faster than your committee can read — is a different kind of hard. AI PhD Survival Guide is a handbook for surviving and finishing an AI or ML PhD without burning out and without falling behind.
Research, stock trading, and startups all share a common pattern: success comes from combining a defensible core competency with the ability to ride trending waves. You don’t need exhaustive preparation anymore. You need methodology and the ability to produce content when it matters. When the right moment arrives, you strike.
A PhD system built on a 19th-century apprenticeship model is failing by nearly every empirical measure — ~40–50% attrition, depression rates six times the general population, and tenure-track placement below 15% in many fields — while venture capital has spent four decades perfecting bilateral contracts that manage exactly the risks PhD programs ignore: information asymmetry, moral hazard, hold-up, and misaligned incentives. The literature across economics, education policy, signaling theory, and AI research converges on a striking conclusion: the structural tools to fix the PhD already exist in VC contract design, but academia has never imported them. This research compendium maps the evidentiary landscape across six domains to ground the argument.
To be totally honest with you, you don’t need to understand the underlying architecture of large language models to get your name on a top-tier AI paper right now, you just need to be a true expert in your own field.
Dr. Zong-Liang Yang’s Land Environment and Atmospheric Dynamics (LEAD) Group at UT-Austin employs satellite remote sensing, earth system modeling, and high-performance computing to advance understanding of Earth system sciences.
If you’re serious about understanding LLMs and AI engineering, Simon Willison’s Newsletter is one of the best resources out there. With over 38,000 subscribers, it provides detailed analysis on AI, LLMs, web engineering, open source, data science, and Python.
Securing up to $150,000 in research funding over three years can define a graduate career, and NASA’s FINESST program is the primary vehicle for that transformation. This guide distills the complex application process into actionable strategies for Earth and Space Science researchers seeking to join the next generation of Future Investigators.
Call it a (10^5) gap if you like, once you put semantic entropy and effective training samples on the board, the difference between internet-scale text and embodied robotics data stops sounding like rhetorical inflation and starts sounding almost conservative. You just have to separate raw physics bits from semantics a learner can actually use.
Lay out every hyped multiAgent product on a table in front of Steve Jobs and he would probably squint, frown, and ask one question, why on earth are you showing the user any of this.
I asked Claude Code a narrow question: can I protect this machine from Codex accidentally deleting files forever, just by aliasing rm to trash? The honest answer turned out to be no, for a reason that is not obvious until you actually test it, and the fix ended up being a five-layer setup rather than a one-liner.
School rankings are a single number standing in for a multi-dimensional decision. School Evaluator is a small web tool that lets you score a school across the dimensions that actually shape your life there. Try Live Demo
Most of biology is averages. You measure a million cells, you get a mean. Eric Greene’s lab figured out how to actually watch one DNA molecule at a time, repair itself, in real time, and that changes what kind of questions biology can ask.
The promise of AI-automated science is intoxicating: imagine machines that can generate hypotheses, design experiments, and publish papers while we sleep.
Most physics undergraduates know Chen Ning Yang as a Nobel laureate and the Y in Yang-Mills. Building him a chronicle made me see something the textbooks gloss over: the most consequential single fact about his life is who his father was, and what that father had set up for him before he was born.
Sometimes a piece of old science fiction stays in your head not because of the gadgets, but because it got the emotional structure of the future right.
The promise of AI-automated science is intoxicating: imagine machines that can generate hypotheses, design experiments, and publish papers while we sleep.
I’ve been playing with mixed-language builds (Fortran calling into C++ and C via iso_c_binding) and wanted a demo that was more interesting than “add two numbers across languages.” So I built fortran-zip-bomb: a small program that generates a genuine ZIP bomb — a small archive that expands into a much larger file on decompression.
Many Chinese teams building embodied AI or AI applications hit the same real-world problem: the domestic models aren’t enough, and they want to call the APIs of foreign models like OpenAI and Anthropic directly. That’s why a swarm of “relay,” “recharge,” and “one OpenAI-compatible interface for you” businesses has sprung up.
Exchanging money for time is a privilege I rarely indulge in, but a surprise membership benefit that cleared airport security in ten minutes changed my perspective on friction and market regulation. While a Clear Plus membership normally costs over a hundred dollars annually, obtaining it for free through an Uber membership allowed me to experience a level of efficiency that money can’t always buy—at least not without a well-regulated system behind it.
I asked Claude Code a narrow question: can I protect this machine from Codex accidentally deleting files forever, just by aliasing rm to trash? The honest answer turned out to be no, for a reason that is not obvious until you actually test it, and the fix ended up being a five-layer setup rather than a one-liner.
In October 2023 I asked ChatGPT an over-engineered question: how do you fry rice so that every grain of rice ends up bonded to egg, with no bare rice grains and no isolated clumps of egg sitting off on their own? I saved that conversation as an HTML file, dropped it in my Downloads folder, and did not look at it again for almost three years. Last week I finally turned it into an actual open-source repo, and going back through the original conversation to build it was more interesting than I expected.
When gold gets too expensive relative to silver, you sell your gold and buy silver. When silver catches up, you swap back. This sounds like folk wisdom, but it’s one of the most time-tested strategies in precious metals.
Most of biology is averages. You measure a million cells, you get a mean. Eric Greene’s lab figured out how to actually watch one DNA molecule at a time, repair itself, in real time, and that changes what kind of questions biology can ask.
Earlier today I published a piece called “Four Ego Mistakes I Made as a 22-Year-Old Founder.” Then I ran it through Gemini 2.5 Pro as an independent reviewer. Gemini’s verdict was that the essay is itself an ego move. I think Gemini is mostly right.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
Decades of Earth-system modeling judgment live in PDFs, mailing lists, and senior researchers’ heads, and none of it is loadable by an AI coding agent. earth-space-ai.org is an attempt to fix that.
At today’s Silicon Valley alumni “Ask a Question” AI meet-up, what I wanted to talk about wasn’t how cool Claude Code is, but how it actually re-slices real work.
I ended up in the wrong NEXUS line at Vancouver International Airport. By the rules, the mistake was mine. By design, it was an almost predictable wrong turn.
Beyond the wayfinding problem that led me into the wrong NEXUS line, my connection at Vancouver International Airport left me with several observations unrelated to signs. I noticed an older-looking mix of people, a departures area that offered almost nowhere to work, and a visible contrast between people in Vancouver and Texas. This post records those observations. The full account of the NEXUS incident is in How I “Reasonably” Ended Up in the Wrong NEXUS Line at YVR.
A university’s favorite performance is to wait until a person no longer needs a medal, then ceremonially drape them in a gown embroidered with the word “Doctor.”
While you’re still grinding your heart out on “if you just work hard enough, you can move up,” you may not realize the system was never designed to cultivate you in the first place, it was designed to screen you.
A laser lightsail accelerating to one percent of light speed turns about one percent of the beam into motion. The other ninety-nine percent leaves as light and does no work.
The same way text foundation models ate NLP and image models ate computer vision, someone is going to build the foundation model that eats spatial reasoning. Gengchen Mai is one of the people taking that bet seriously, and his SEAI Lab at UT Austin is one of the places it is being built.
Hah, I can’t help but laugh. It just hit me: the first time I ever used Markdown was back when I was building a poetry society. And that’s also when I first learned about Git. Looking back now, if you put all the founding members of that poetry society together, you’d almost have two unicorns.
Many Chinese teams building embodied AI or AI applications hit the same real-world problem: the domestic models aren’t enough, and they want to call the APIs of foreign models like OpenAI and Anthropic directly. That’s why a swarm of “relay,” “recharge,” and “one OpenAI-compatible interface for you” businesses has sprung up.
Earlier today I published a piece called “Four Ego Mistakes I Made as a 22-Year-Old Founder.” Then I ran it through Gemini 2.5 Pro as an independent reviewer. Gemini’s verdict was that the essay is itself an ego move. I think Gemini is mostly right.
People love saying that ten years to a billion-dollar valuation is the normal pace for a unicorn, neither fast nor slow. But once you actually crunch the compound numbers, you realize what hides behind that word “normal” is a beast that doubles in value every single year.
If you’ve been watching the business map of the AI track lately, you can’t help but be shaken by that trend feverishly racing from “human-machine collaboration” toward “multi-agent autonomy.”
Lay out every hyped multiAgent product on a table in front of Steve Jobs and he would probably squint, frown, and ask one question, why on earth are you showing the user any of this.
Yuxuan and I have been discussing AI agent ideas for a while. Yesterday, we finally decided: we’re building Atomize, a task-breaking agent system evolved from Goblin Tools.
A bit of history from a casual chat: in the US, science students used to get bigger stipends than business, law or medicine students, because science students were poor.
Lay out every hyped multiAgent product on a table in front of Steve Jobs and he would probably squint, frown, and ask one question, why on earth are you showing the user any of this.
Research, stock trading, and startups all share a common pattern: success comes from combining a defensible core competency with the ability to ride trending waves. You don’t need exhaustive preparation anymore. You need methodology and the ability to produce content when it matters. When the right moment arrives, you strike.
The signal truly worth heeding is not that AI companies are growing too slowly, but that they are growing fast while cash-flow pressure keeps mounting.
UT01 is a free, student-built collection of resources for The University of Texas at Austin. It brings practical campus information and community projects into one public site.
The sense of agency that took me more than twenty years to grow, these seventeen and eighteen year old students got far more easily, just by being at Stanford, being in America, or maybe going to high school in Shanghai first.
On a stormy Sunday afternoon in 1988, Edmund Clarke, a Carnegie Mellon professor and Turing Award winner, came to lecture at Fudan University and found the room nearly empty.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
A PhD is hard. A PhD in 2026 — with the field moving faster than your committee can read — is a different kind of hard. AI PhD Survival Guide is a handbook for surviving and finishing an AI or ML PhD without burning out and without falling behind.
Every knowledge worker is now competing with an LLM for some part of their job. AI Survival Guide is a handbook for figuring out which parts, what to do about it, and how to come out the other side better at your craft instead of replaced by it.
The US is full of small traps that nobody warns you about until after you’ve fallen into one. US Survival Guide is a handbook for Chinese students and newcomers on identifying risk early, knowing your rights, and building a financial defense before you need it. Read the Guide
I’ve been playing with mixed-language builds (Fortran calling into C++ and C via iso_c_binding) and wanted a demo that was more interesting than “add two numbers across languages.” So I built fortran-zip-bomb: a small program that generates a genuine ZIP bomb — a small archive that expands into a much larger file on decompression.
The roar of cooling systems in the Texas Advanced Computing Center (TACC) isn’t just noise—it’s the power of supercomputers translating the overwhelming dimensionality of climate data into something students can finally see and understand.
The promise of AI-automated science is intoxicating: imagine machines that can generate hypotheses, design experiments, and publish papers while we sleep.
On a stormy Sunday afternoon in 1988, Edmund Clarke, a Carnegie Mellon professor and Turing Award winner, came to lecture at Fudan University and found the room nearly empty.
I spent a whole evening with Gemini taking apart the Buy Borrow Die playbook that American billionaires run, expecting that with a little scaling down I could just copy the moves, and what I found instead was that almost every single move has an F-1 trapdoor underneath it, and the list of things I can actually do fits on one page.
The silence surrounding the Alamo chapel in San Antonio belies the brutal, thirteen-day siege that transformed this former Spanish mission into the ultimate symbol of Texan independence. Standing before its weathered facade today, one can almost hear the echoes of a conflict that remains one of the most legendary chapters in American history.
Port Aransas South Jetty published an Institute Insights feature on May 28, 2026 about how our University of Texas team is using satellite remote sensing and AI to monitor Texas coastal water quality.
Hah, I can’t help but laugh. It just hit me: the first time I ever used Markdown was back when I was building a poetry society. And that’s also when I first learned about Git. Looking back now, if you put all the founding members of that poetry society together, you’d almost have two unicorns.
People love saying that ten years to a billion-dollar valuation is the normal pace for a unicorn, neither fast nor slow. But once you actually crunch the compound numbers, you realize what hides behind that word “normal” is a beast that doubles in value every single year.
Top physics researchers aren’t blind to what AI is doing in the application layer. They’re locked by their own evaluation system and can’t afford to look.
Sometimes a piece of old science fiction stays in your head not because of the gadgets, but because it got the emotional structure of the future right.
Every generation has its own way of managing work: paper notebooks, SaaS task managers, and now programmable agentic workflows powered by tools like OpenClaw heartbeat.
I spent a whole evening with Gemini taking apart the Buy Borrow Die playbook that American billionaires run, expecting that with a little scaling down I could just copy the moves, and what I found instead was that almost every single move has an F-1 trapdoor underneath it, and the list of things I can actually do fits on one page.
When gold gets too expensive relative to silver, you sell your gold and buy silver. When silver catches up, you swap back. This sounds like folk wisdom, but it’s one of the most time-tested strategies in precious metals.
thoughts
The Mindset of Disruptive Innovators
What Did the People Who Changed the World Actually See?
An Epistemic Crisis in an Age of Abundance
25 minute read
Published:
What do the people who change the world see that ordinary people can’t?
A hand-controlled 3D visualization of your AI conversation history - fly through ChatGPT conversations and explore artificial intelligence concepts. Try Live Demo
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
TQQQ is the 3x-leveraged Nasdaq-100 ETF. It is also one of the most asymmetric instruments retail investors touch — the upside is real, the drawdowns are brutal, and the daily-rebalance math means buy-and-hold doesn’t behave the way most people assume. TQQQ ML Trend is an experiment in using machine learning to predict the trend regime, not the price.
The Tmux Orchestrator enables Claude agents to work autonomously, schedule their own check-ins, and coordinate across multiple projects without human intervention - a project I explored and learned a lot from.
Every indie developer who has ever burned through a free API tier knows the feeling: you build something cool, and then your OPENAI_API_KEY runs out at the worst possible moment. hao-tokens is a curated list of the legitimate ways to get free or low-cost LLM tokens so you can keep building.
TQQQ is the 3x-leveraged Nasdaq-100 ETF. It is also one of the most asymmetric instruments retail investors touch — the upside is real, the drawdowns are brutal, and the daily-rebalance math means buy-and-hold doesn’t behave the way most people assume. TQQQ ML Trend is an experiment in using machine learning to predict the trend regime, not the price.
TQQQ is the 3x-leveraged Nasdaq-100 ETF. It is also one of the most asymmetric instruments retail investors touch — the upside is real, the drawdowns are brutal, and the daily-rebalance math means buy-and-hold doesn’t behave the way most people assume. TQQQ ML Trend is an experiment in using machine learning to predict the trend regime, not the price.
When gold gets too expensive relative to silver, you sell your gold and buy silver. When silver catches up, you swap back. This sounds like folk wisdom, but it’s one of the most time-tested strategies in precious metals.
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
A receipt in Singapore showed S$5.50, while a U.S. credit-card account displayed only US$4.27. Another purchase of about S$48 appeared as roughly US$38. A bank-card transit ride also failed to appear immediately as pending.
The thing that almost stranded me on this international trip was not a typhoon, but several unrelated systems deciding at the same time that they did not trust me.
The silence surrounding the Alamo chapel in San Antonio belies the brutal, thirteen-day siege that transformed this former Spanish mission into the ultimate symbol of Texan independence. Standing before its weathered facade today, one can almost hear the echoes of a conflict that remains one of the most legendary chapters in American history.
At the Metropolitan Museum of Art in New York, I walked into a real ancient Egyptian tomb, not a replica or a model, but a tomb that stood in the Egyptian desert more than four thousand years ago and was moved whole to Manhattan.
Exchanging money for time is a privilege I rarely indulge in, but a surprise membership benefit that cleared airport security in ten minutes changed my perspective on friction and market regulation. While a Clear Plus membership normally costs over a hundred dollars annually, obtaining it for free through an Uber membership allowed me to experience a level of efficiency that money can’t always buy—at least not without a well-regulated system behind it.
On May 17, 2025, I had about nine hours alone in Hong Kong between flights and trains, and I planned them around Victoria Harbour and the city’s richest commercial districts.
I plugged a Western Digital external drive full of data into a MacBook Air, tried to copy a file onto it, and nothing happened. No error dialog, no progress bar, just a drive that would let me read everything and write nothing. My first instinct was that something was broken, or that I needed to fix permissions. Both were wrong, and chasing the wrong explanation almost led me to permanently downgrade the security of the whole laptop.
我把一块装满数据的西部数据(WD)移动硬盘插到 MacBook Air 上,想往里拷一个文件,结果什么都没发生。没有报错弹窗,没有进度条,就是一块能读出所有东西、却一个字节都写不进去的硬盘。我的第一反应是它坏了,或者是我得去修一下权限。这两个判断都是错的,而且顺着错误的解释找下去,差点让我把整台笔记本的安全性永久降级。
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
Most crypto dashboards either drown you in numbers or hide the signal behind a paywall. Crypto Dashboard is my attempt at a clean, AI-augmented view of the market that runs entirely in your browser. Try Live Demo
School rankings are a single number standing in for a multi-dimensional decision. School Evaluator is a small web tool that lets you score a school across the dimensions that actually shape your life there. Try Live Demo
Exchanging money for time is a privilege I rarely indulge in, but a surprise membership benefit that cleared airport security in ten minutes changed my perspective on friction and market regulation. While a Clear Plus membership normally costs over a hundred dollars annually, obtaining it for free through an Uber membership allowed me to experience a level of efficiency that money can’t always buy—at least not without a well-regulated system behind it.
People love saying that ten years to a billion-dollar valuation is the normal pace for a unicorn, neither fast nor slow. But once you actually crunch the compound numbers, you realize what hides behind that word “normal” is a beast that doubles in value every single year.
The US is full of small traps that nobody warns you about until after you’ve fallen into one. US Survival Guide is a handbook for Chinese students and newcomers on identifying risk early, knowing your rights, and building a financial defense before you need it. Read the Guide
Port Aransas South Jetty published an Institute Insights feature on May 28, 2026 about how our University of Texas team is using satellite remote sensing and AI to monitor Texas coastal water quality.
The talk that stayed with me at the Texas Symposium on Machine Learning, Responsible AI & Robotics 2026 was about extending language models, not just making them bigger.
AlphaEarthHack is the project our team built for the UT Austin Geoscience Hackathon. The goal: see how far we could push AI on Earth system data inside a single weekend. Try Live Demo
UT01 is a free, student-built collection of resources for The University of Texas at Austin. It brings practical campus information and community projects into one public site.
Most people think of summer vacation as time off. I started wondering whether that framing undersells it. Summer Calculator is a small web tool that estimates the full value of your summer — money, learning, relationships, health — not just the days you didn’t work. Try Live Demo
People love saying that ten years to a billion-dollar valuation is the normal pace for a unicorn, neither fast nor slow. But once you actually crunch the compound numbers, you realize what hides behind that word “normal” is a beast that doubles in value every single year.
Most land surface models treat a tree like a passive straw. Water comes in at the roots, water leaves at the leaves, end of story. Ashley Matheny’s research basically says no, a tree is an active hydraulic system with storage, capacitance, and a strategy, and if you do not model it that way you are going to be wrong about drought.
Virtual cell models powered by neuromorphic computing and gene language models represent one of the most capital-intensive and scientifically ambitious convergences in biotech AI. If you’re evaluating this space as a VC intern, you need to understand three core components: what these systems actually do, why the market is moving now, and where the investable opportunities lie.
A PhD system built on a 19th-century apprenticeship model is failing by nearly every empirical measure — ~40–50% attrition, depression rates six times the general population, and tenure-track placement below 15% in many fields — while venture capital has spent four decades perfecting bilateral contracts that manage exactly the risks PhD programs ignore: information asymmetry, moral hazard, hold-up, and misaligned incentives. The literature across economics, education policy, signaling theory, and AI research converges on a striking conclusion: the structural tools to fix the PhD already exist in VC contract design, but academia has never imported them. This research compendium maps the evidentiary landscape across six domains to ground the argument.
At today’s Silicon Valley alumni “Ask a Question” AI meet-up, what I wanted to talk about wasn’t how cool Claude Code is, but how it actually re-slices real work.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
I contributed to the startup documentary Starting Point One. The film records early-stage builders and the choices behind starting something from zero.
I appeared in Episode 1 of Mango TV’s Gold Rush 2026 (《夺金2026》) as a young founder working in Austin. The segment offers a brief television snapshot of the projects and questions I was pursuing at the time.
Virtual cell models powered by neuromorphic computing and gene language models represent one of the most capital-intensive and scientifically ambitious convergences in biotech AI. If you’re evaluating this space as a VC intern, you need to understand three core components: what these systems actually do, why the market is moving now, and where the investable opportunities lie.
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
The roar of cooling systems in the Texas Advanced Computing Center (TACC) isn’t just noise—it’s the power of supercomputers translating the overwhelming dimensionality of climate data into something students can finally see and understand.
A hand-controlled 3D visualization of your AI conversation history - fly through ChatGPT conversations and explore artificial intelligence concepts. Try Live Demo
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
Warren Buffett: The “Open Source” Leader Half a Century Before GitHub
巴菲特:比GitHub早了半个世纪的“开源”运动领袖
2 minute read
Published:
In an era driven by code, collaboration, and transparency, GitHub has become synonymous with the “open source” spirit. But if we turn our gaze to the world of finance, we find a pioneer of “open source” who predates the birth of GitHub by a full half-century. His name is Warren Buffett.
I ended up in the wrong NEXUS line at Vancouver International Airport. By the rules, the mistake was mine. By design, it was an almost predictable wrong turn.
“这b人生过的值不值” — roughly, “was this damn life worth it?” — is a phrase that does a lot of emotional work on the Chinese internet. ZuoGuoHuaDiao (做过划掉) is a small web tool that takes the phrase seriously and tries to answer it with numbers. Try Live Demo
Most people think of summer vacation as time off. I started wondering whether that framing undersells it. Summer Calculator is a small web tool that estimates the full value of your summer — money, learning, relationships, health — not just the days you didn’t work. Try Live Demo
UT01 is a free, student-built collection of resources for The University of Texas at Austin. It brings practical campus information and community projects into one public site.
A handcrafted website universe where every webpage, balloon, click, and line of code says “I love you” - designed exclusively for Momo. Visit Live Site
Today I had an interesting experience collaborating with Claude Code to completely overhaul my personal academic website. As a PhD student in Geological and Earth Sciences at UT Austin, I needed to update my GitHub Pages site with real professional information instead of the placeholder content that had been sitting there.
From the vast datasets of Earth System Models to the specialized niches of high-performance computing, this space documents my journey as a PhD student at UT Austin pushing the boundaries of Geological and Earth Sciences. This website is more than just a portfolio—it’s a hub where data-driven climate science meets the practical challenges of modern research.
I plugged a Western Digital external drive full of data into a MacBook Air, tried to copy a file onto it, and nothing happened. No error dialog, no progress bar, just a drive that would let me read everything and write nothing. My first instinct was that something was broken, or that I needed to fix permissions. Both were wrong, and chasing the wrong explanation almost led me to permanently downgrade the security of the whole laptop.
我把一块装满数据的西部数据(WD)移动硬盘插到 MacBook Air 上,想往里拷一个文件,结果什么都没发生。没有报错弹窗,没有进度条,就是一块能读出所有东西、却一个字节都写不进去的硬盘。我的第一反应是它坏了,或者是我得去修一下权限。这两个判断都是错的,而且顺着错误的解释找下去,差点让我把整台笔记本的安全性永久降级。
Every generation has its own way of managing work: paper notebooks, SaaS task managers, and now programmable agentic workflows powered by tools like OpenClaw heartbeat.
Earth system models are some of the most complex scientific software ever written, and they are also some of the worst-documented for newcomers. I have been building a series of “skill packages” — structured, progressive-disclosure knowledge bundles — for the major Earth system and land surface models, designed to be used by both new graduate students and AI coding agents.
When an AI writing assistant turns a paper’s incoherent rambling into a “well-structured pile of something,” we have to admit: it is basically a cyber laxative.
Ask which campus actually sits on the best multimodal feedstock for GPT-4V-class perception, Sora-class video, Gemini-scale bundles, and Meta Emu-style image stacks, and the short answer is almost vulgar in how cleanly it splits three big piles. Meta still pulls ahead by a chasm on stills, ByteDance owns the high-velocity short-video river that is really motion plus audio, and X ships the smallest absolute media volume yet the weirdest leverage on tight text-image coupling and live-event semantics.
On a United Airlines flight from San Francisco SFO to Shanghai Pudong PVG, the plane had started its descent and the cabin announcements kept reminding everyone to fasten their seatbelts. Outside was night; inside, people were already lit up with the excitement of “finally going home.” It was on this flight that I met a friend.
I’ve been discussing this question with a friend lately. He wants to use AI for matching in the dating market; I think with a small sample size this is perfectly feasible, you don’t even need to build any search/ads/rec system at all. Just ask the large language model directly, toss in a few users’ profiles, and have it rank them; the whole process is very simple.
Anthropic’s most ruthless move isn’t polishing every product to perfection before release, but daring to throw out a research preview first, then rapidly getting stronger in front of everyone.
Hah, I can’t help but laugh. It just hit me: the first time I ever used Markdown was back when I was building a poetry society. And that’s also when I first learned about Git. Looking back now, if you put all the founding members of that poetry society together, you’d almost have two unicorns.
Many Chinese teams building embodied AI or AI applications hit the same real-world problem: the domestic models aren’t enough, and they want to call the APIs of foreign models like OpenAI and Anthropic directly. That’s why a swarm of “relay,” “recharge,” and “one OpenAI-compatible interface for you” businesses has sprung up.
Anthropic’s most ruthless move isn’t polishing every product to perfection before release, but daring to throw out a research preview first, then rapidly getting stronger in front of everyone.
I’ve been discussing this question with a friend lately. He wants to use AI for matching in the dating market; I think with a small sample size this is perfectly feasible, you don’t even need to build any search/ads/rec system at all. Just ask the large language model directly, toss in a few users’ profiles, and have it rank them; the whole process is very simple.
The most important thing is selling. Having technology is useless; it only matters if someone is willing to buy. I don’t think anyone has a real tech moat; that part is easy to solve. As long as you have a little technical foundation, you can handle it. What matters most is that people come and buy. Though, it might be that my own technical level is too high, and I’ve grown numb to technology.
The most terrifying thing about Silicon Valley has never been the brilliant ideas of geniuses, but that it established an entire system of mechanisms that encourage “creative betrayal.”
Doing a PhD cannot rely on “felt effort” and “moving yourself emotionally.” We need to upgrade day-to-day literature reading, experiment design, data analysis, and paper writing into a personal research system that is quantifiable, reviewable, and continuously optimizable. The point is not self-exploitation, but verifying whether your research efficiency truly exists, and keeping precious PhD time from being consumed inefficiently.
Compute / tokens are the new generation of free eggs. Right now all the big vendors are handing out compute like they’re handing out eggs. When you’re old, you’ll be fighting other old grannies and grandpas for free eggs, this is no longer just a joke, it might be reality.
When a random idea hits you on a US campus to slip a ballistic plate into the North Face backpack you carry every day, things start racing toward cyberpunk.
In statistics, how you find outliers depends on the dimensionality of your data, its distributional characteristics, and your tolerance for what counts as “abnormal.” Here are the most common and standard approaches:
When a random idea hits you on a US campus to slip a ballistic plate into the North Face backpack you carry every day, things start racing toward cyberpunk.
The most important thing is selling. Having technology is useless; it only matters if someone is willing to buy. I don’t think anyone has a real tech moat; that part is easy to solve. As long as you have a little technical foundation, you can handle it. What matters most is that people come and buy. Though, it might be that my own technical level is too high, and I’ve grown numb to technology.
The most terrifying thing about Silicon Valley has never been the brilliant ideas of geniuses, but that it established an entire system of mechanisms that encourage “creative betrayal.”
The most important thing is selling. Having technology is useless; it only matters if someone is willing to buy. I don’t think anyone has a real tech moat; that part is easy to solve. As long as you have a little technical foundation, you can handle it. What matters most is that people come and buy. Though, it might be that my own technical level is too high, and I’ve grown numb to technology.
I’ve been discussing this question with a friend lately. He wants to use AI for matching in the dating market; I think with a small sample size this is perfectly feasible, you don’t even need to build any search/ads/rec system at all. Just ask the large language model directly, toss in a few users’ profiles, and have it rank them; the whole process is very simple.
Doing a PhD cannot rely on “felt effort” and “moving yourself emotionally.” We need to upgrade day-to-day literature reading, experiment design, data analysis, and paper writing into a personal research system that is quantifiable, reviewable, and continuously optimizable. The point is not self-exploitation, but verifying whether your research efficiency truly exists, and keeping precious PhD time from being consumed inefficiently.
On a United Airlines flight from San Francisco SFO to Shanghai Pudong PVG, the plane had started its descent and the cabin announcements kept reminding everyone to fasten their seatbelts. Outside was night; inside, people were already lit up with the excitement of “finally going home.” It was on this flight that I met a friend.
In statistics, how you find outliers depends on the dimensionality of your data, its distributional characteristics, and your tolerance for what counts as “abnormal.” Here are the most common and standard approaches:
Although “umami” is the unshakable soul of Jiangsu-Zhejiang and Cantonese cooking, in traditional American food you often wander only among single-note salt, sweet, and oil, struggling to find that layered depth of flavor. That isn’t accidental; it’s the inevitable result of a deep cultural difference in how ingredients are handled, how seasoning is reasoned, and how industrial production works.
On a United Airlines flight from San Francisco SFO to Shanghai Pudong PVG, the plane had started its descent and the cabin announcements kept reminding everyone to fasten their seatbelts. Outside was night; inside, people were already lit up with the excitement of “finally going home.” It was on this flight that I met a friend.
Doing a PhD cannot rely on “felt effort” and “moving yourself emotionally.” We need to upgrade day-to-day literature reading, experiment design, data analysis, and paper writing into a personal research system that is quantifiable, reviewable, and continuously optimizable. The point is not self-exploitation, but verifying whether your research efficiency truly exists, and keeping precious PhD time from being consumed inefficiently.
The most terrifying thing about Silicon Valley has never been the brilliant ideas of geniuses, but that it established an entire system of mechanisms that encourage “creative betrayal.”
You apply to Anthropic, land an offer, then ask HR whether they’ll sponsor your PERM, and they say “on hold for now” or change the subject, and you probably stand there frozen.
You apply to Anthropic, land an offer, then ask HR whether they’ll sponsor your PERM, and they say “on hold for now” or change the subject, and you probably stand there frozen.
Compute / tokens are the new generation of free eggs. Right now all the big vendors are handing out compute like they’re handing out eggs. When you’re old, you’ll be fighting other old grannies and grandpas for free eggs, this is no longer just a joke, it might be reality.
In statistics, how you find outliers depends on the dimensionality of your data, its distributional characteristics, and your tolerance for what counts as “abnormal.” Here are the most common and standard approaches:
You apply to Anthropic, land an offer, then ask HR whether they’ll sponsor your PERM, and they say “on hold for now” or change the subject, and you probably stand there frozen.
On a United Airlines flight from San Francisco SFO to Shanghai Pudong PVG, the plane had started its descent and the cabin announcements kept reminding everyone to fasten their seatbelts. Outside was night; inside, people were already lit up with the excitement of “finally going home.” It was on this flight that I met a friend.
Although “umami” is the unshakable soul of Jiangsu-Zhejiang and Cantonese cooking, in traditional American food you often wander only among single-note salt, sweet, and oil, struggling to find that layered depth of flavor. That isn’t accidental; it’s the inevitable result of a deep cultural difference in how ingredients are handled, how seasoning is reasoned, and how industrial production works.
You apply to Anthropic, land an offer, then ask HR whether they’ll sponsor your PERM, and they say “on hold for now” or change the subject, and you probably stand there frozen.
Compute / tokens are the new generation of free eggs. Right now all the big vendors are handing out compute like they’re handing out eggs. When you’re old, you’ll be fighting other old grannies and grandpas for free eggs, this is no longer just a joke, it might be reality.
When a random idea hits you on a US campus to slip a ballistic plate into the North Face backpack you carry every day, things start racing toward cyberpunk.
The most important thing is selling. Having technology is useless; it only matters if someone is willing to buy. I don’t think anyone has a real tech moat; that part is easy to solve. As long as you have a little technical foundation, you can handle it. What matters most is that people come and buy. Though, it might be that my own technical level is too high, and I’ve grown numb to technology.
There are only 26 single-letter .ai domains. I went through all of them, one by one, to see who actually builds something and who just squats. The answer: about six run real products, one belongs to Elon Musk, one belongs to Google, one apparently belongs to Apple without a website, and the rest are for-sale pages asking between 1.5 and 500 million dollars. Here is the full alphabet.
Compute / tokens are the new generation of free eggs. Right now all the big vendors are handing out compute like they’re handing out eggs. When you’re old, you’ll be fighting other old grannies and grandpas for free eggs, this is no longer just a joke, it might be reality.
When a random idea hits you on a US campus to slip a ballistic plate into the North Face backpack you carry every day, things start racing toward cyberpunk.
The most terrifying thing about Silicon Valley has never been the brilliant ideas of geniuses, but that it established an entire system of mechanisms that encourage “creative betrayal.”
The most terrifying thing about Silicon Valley has never been the brilliant ideas of geniuses, but that it established an entire system of mechanisms that encourage “creative betrayal.”
Although “umami” is the unshakable soul of Jiangsu-Zhejiang and Cantonese cooking, in traditional American food you often wander only among single-note salt, sweet, and oil, struggling to find that layered depth of flavor. That isn’t accidental; it’s the inevitable result of a deep cultural difference in how ingredients are handled, how seasoning is reasoned, and how industrial production works.
Although “umami” is the unshakable soul of Jiangsu-Zhejiang and Cantonese cooking, in traditional American food you often wander only among single-note salt, sweet, and oil, struggling to find that layered depth of flavor. That isn’t accidental; it’s the inevitable result of a deep cultural difference in how ingredients are handled, how seasoning is reasoned, and how industrial production works.